|
August 2026 ITL FOCUS: Operational Efficiency
ITL FOCUS is a monthly initiative featuring topics related to innovation in risk management and insurance.


Discover 'The Future of Risk™': Innovation, Tech, & Disruption Insights from Industry Leaders!
ITL FOCUS is a monthly initiative featuring topics related to innovation in risk management and insurance.
|
Get Involved
Our authors are what set Insurance Thought Leadership apart.
|
Partner with us
We’d love to talk to you about how we can improve your marketing ROI.
|

Insurance Thought Leadership (ITL) delivers engaging, informative articles from our global network of thought leaders and decision makers. Their insights are transforming the insurance and risk management marketplace through knowledge sharing, big ideas on a wide variety of topics, and lessons learned through real-life applications of innovative technology.
We also connect our network of authors and readers in ways that help them uncover opportunities and that lead to innovation and strategic advantage.
AI can answer questions correctly yet still fail when it doesn't recognize task shifts, context, or consequences.
"Should AI stand in the customer's shoes?"
That idea struck me as fresh the first time I heard it. But the more I sat with it, the less it seemed to mean — if it only means presenting results through language and interfaces users are already familiar with, the payoff is thin.
Looking back at the AI projects I've been part of, I've come to a different conclusion: a model can answer a question correctly and still have no idea what task the person is actually trying to complete — whether the right move now is to keep answering, ask a follow-up, stop, or hand off to a human. For AI to take on real work, not just answer questions, companies need to translate what experienced professionals know about context, risk, timing, and consequence into something a system can actually recognize: signals, task states, response protocols, and validation criteria.
This piece starts from a scenario I know well — model testing — and walks through how that translation happens, and why it forms two decisive thresholds standing between AI and real deployment. AI companies that understand and clear these thresholds are better positioned to build durable capabilities within a vertical domain, turning what they learn from a single deployment into delivery capabilities that are repeatable, verifiable, and scalable.
On most AI projects, technical teams build a battery of test prompts and run the model against them repeatedly. Did it identify intent correctly? Did it retrieve and apply the right knowledge? Was the answer stable, and free of hallucination, policy violations, or logical errors? That's the bulk of testing and debugging.
I've watched this play out on my own company's projects many times. In a field like insurance sales, though, the testing team often also includes experienced domain experts sitting alongside the engineers. They read the same conversations and flag the same kinds of issues — but they're looking through a different lens entirely.
The technical team asks first whether the model got the answer right. The domain expert asks something else: does this answer fit where the conversation is right now? Where does it take the customer? And what should happen next — keep answering, probe further, pull back, or bring in a human?
That gap between the two lenses is exactly what most AI projects run into the moment they move from model testing into a live business setting.
Say a critical illness policy includes a 90-day waiting period — a clause under which coverage for specified illnesses begins only after a set period, subject to the policy terms. A customer, mid-conversation with a sales assistant, asks: "How long is the waiting period on this critical illness policy?"
The AI checks the policy and answers: "The waiting period is 90 days. A covered illness first diagnosed after that point is eligible for a claim under the policy terms."
Judged purely on product knowledge and wording, nothing is wrong here. The model understood the question, cited the correct clause, and made no promise beyond what the policy covers. By ordinary QA standards, this counts as a clean, successful response.
But an experienced insurance agent may notice something a conventional QA review would miss: why is this customer asking about the waiting period right now?
Maybe they're simply comparing products. Or maybe they just had a checkup, noticed a symptom, or are quietly worried about a health issue that hasn't been diagnosed yet. The same question, asked against a different backdrop, can send the rest of the conversation in an entirely different direction.
What this threshold really tests is whether the AI can register that the task itself has shifted. The system first must notice what's happening: is this still a routine product inquiry, or has the task already shifted toward clarifying health risks, disclosure obligations, and coverage expectations?
If the customer is simply comparing products, stating the waiting period is enough. But if they've already mentioned something like an abnormal test result or a health concern, that same product inquiry has likely moved into different territory.
If the AI, still optimizing for conversion, nudges the customer to buy now so the waiting period starts ticking sooner — every individual line in that exchange might still look defensible on its own, and the short-term conversion numbers might even look good. But measured against the actual job — a sound, compliant sale — the direction has already gone wrong. That drift is hard to catch precisely because each individual output holds up fine under its own scrutiny; the problem only shows up once you look at where the pieces are heading together.
From a human-AI interaction standpoint, the customer opened with a product question, but the task that actually needed handling may have quietly turned into something else mid-conversation. The model answered correctly. It just never noticed the nature of the job had changed.
Recognizing that a task has shifted only answers "what's happening right now." The AI still needs to understand what the task is meant to accomplish, and what the next move might set in motion.
This kind of failure is hard to catch through accuracy checks alone. Sometimes the problem is missing sufficient probing before the answer. Sometimes it's an inappropriate action taken after answering.
A customer asking a service rep about refund policy may have already been through several failed attempts and actually need an escalation, not a repeat of the rules. A sales manager asking AI to explain a revenue decline might be heading toward a decision about which customer segments to cut, which frontline process to change, or how to reallocate resources. A customer asking about a specific policy clause might simply have a preference — or might be quietly weighing a risk they haven't said out loud.
Language and knowledge let AI produce a better answer. But taking on real work requires understanding the task at hand: its current state, its intended goal, and the consequences of the next action.
This threshold tests whether AI understands the context and goal behind the task — not just that the task has changed, but where it has moved to, what information is still missing, and what should happen next.
Only with that in place does "AI standing in the customer's shoes" mean anything concrete. A natural tone, a clean interface, a flexible dashboard — these all improve how information gets seen and used. Understanding the task itself is a different matter altogether: it reaches into timing, limits, action, and who's accountable for what.
The gap between the engineers and the domain experts isn't really about who knows the technology and who knows the business. The real difference is in the basic unit each side uses to judge whether an output is any good. By "unit," I mean: when you're deciding whether one output is acceptable, what's the first thing you look at? The technical team checks the model against a set of evaluation dimensions — intent recognition, retrieval accuracy, answer quality, safety constraints, output stability. The domain expert puts that same answer back into its full context: when did it show up, where is the customer in the process, and what could it lead to?
So the engineer's first move is to check the answer itself. The domain expert cares more about where that answer sits within the whole job: does it fit the moment, could it be misread, and how does it affect trust, compliance, and the eventual business outcome? That difference in unit of judgment has real consequences for how well human and AI work together. A model can look great in a test report and still keep producing the wrong response once it's live — and the problem often isn't the content of the answer at all. It's that the system never noticed the task had already changed.
A good domain expert can often flag a problem instantly: "That's not something you say here." For an AI team, that sentence is just a starting point. It raises questions that still need answers: what signal did the expert notice? What outcome were they worried about? Which situations are fine to keep going, and which need a follow-up question or a handoff? And where does that knowledge belong — the system prompt, the context, a rule, a workflow, or a hard permission boundary in the system itself?
No matter how sharp someone's professional judgment is, if it stays locked inside their own intuition, it can never become a system capability that scales. So the real question — the one that determines whether a team clears both thresholds — is how to turn expert instinct into structures the system can recognize, execute, and validate.
Bringing domain expertise into an AI system tends to follow a fairly consistent path:
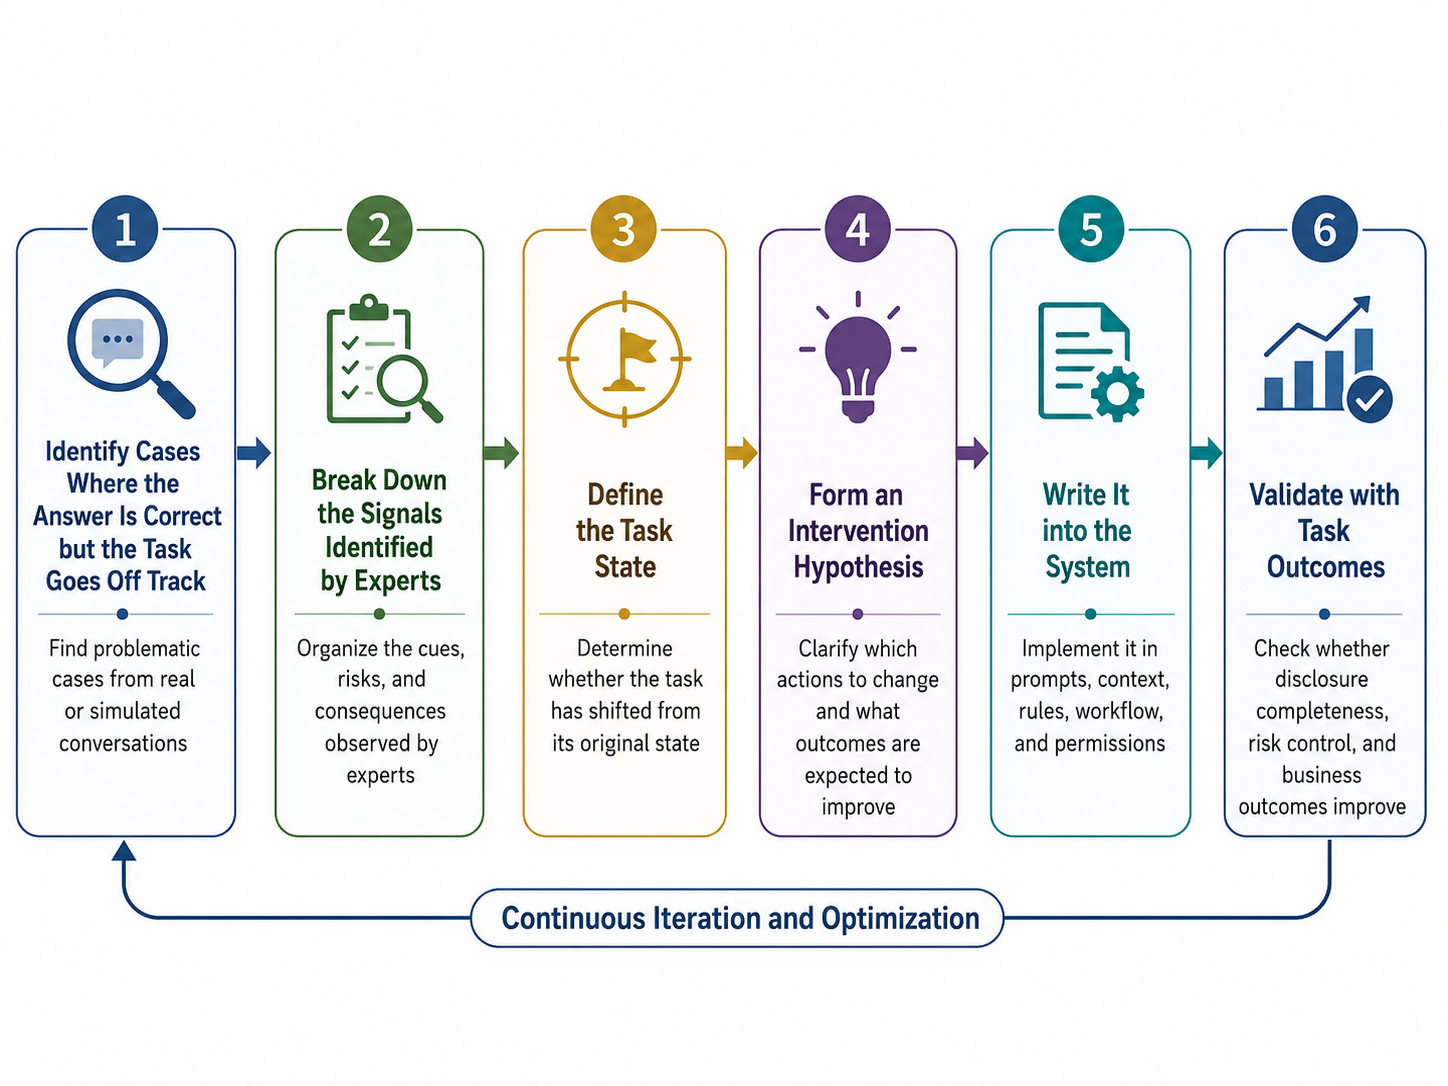
It starts with finding real cases where the model answered correctly but the task still went off course. From there, the team breaks down exactly what signal the expert picked up on, and uses that to define the task state that signal points to. Only then does the team frame a concrete hypothesis about what intervention might help — and only after that does any of it get written into the system, tested against real outcomes, and refined according to the results.
That process has to start from a concrete case. Ask an expert in the abstract what to watch for during a sale, and you'll mostly get principles. Put an actual — or simulated — conversation in front of them and ask where the problem first started, and the instincts they've built up over years, the ones they've never quite put into words, finally have something to attach to.
Take the waiting-period case. A customer mentioning a recent checkup, a physical symptom, asking "is it too late to buy now," or treating the waiting period as some kind of guarantee of a future payout — these are all signals worth flagging. But a signal is just an observation. Plenty of people who ask about a waiting period have no health issue at all, and the model shouldn't jump to conclusions off a single word. The team still must work out under what conditions a given signal indicates the task has shifted.
Once that shift is defined — a routine product inquiry moving into a health-risk and disclosure conversation — the system can change how it responds: instead of pushing forward, it clarifies the risk, and hands off to a human if needed.
Through this process, an expert's instinct gradually turns into signals and task states the system can recognize. Once a task state is defined, the team still has to answer something more fundamental:
For a customer showing a possible health concern, does one extra clarifying question — instead of answering directly and pushing the sale forward — improve the completeness of health disclosure and reduce downstream disputes?
That question still lives at the level of a business hypothesis and an intervention design — it hasn't yet become a prompt or a system rule. It defines who it applies to, what action to test, what to compare it against, and what outcome it's meant to improve. At this point, the team has moved past "what should AI say" and into "does changing what AI does actually change the business result?"
From there, the technical team has to engineer the hypothesis itself. First: which signals should trigger the risk-clarification path. Then: what the system should do once triggered. For example — when a customer asks about the waiting period and also mentions a recent checkup, a symptom, or timing around the purchase, the AI should first understand why they're asking, flag the importance of honest disclosure and underwriting review, avoid implying a claim is guaranteed, and escalate to a human when necessary.
Some of this belongs in the system prompt. Other parts require context, annotation, rules, state management, and workflow support to work together. Where compliance lines, commitment authority, or high-stakes decisions are involved, tighter system-level guardrails are usually required too.
Bringing expert judgment into a system, in other words, can't be done with a single block of prompt text. The team must work out, piece by piece, which layer each bit of knowledge, experience, and constraint belongs in — that is what reliably constrains model behavior and improves the consistency of both outputs and actions.
Once the system design changes, the testing standard has to change with it. In a routine product comparison, the AI can simply state the waiting period. When a customer mentions an abnormal test result and asks whether it's too late to buy, the system needs to recognize a different task state and adjust its handling accordingly. If the customer then asks the AI to help conceal a health issue, it should stop, explain the disclosure requirement, and route the conversation to a qualified human.
And in the end, it all comes back to real outcomes. Did the extra question improve disclosure completeness and cut down on disputes? Did it create friction, interrupting a large share of routine inquiries that never needed it? Did the human handoff genuinely improve customer understanding and underwriting quality?
These questions only get answered against real data over time. It's only once expert judgment enters that loop — test, deploy, measure, refine — that it has a chance to settle into something stable and repeatable.
What a given project needs to deliver shapes what human-AI collaboration ends up looking like. If a partner cares most about the final sales result, UI/UX may not be the primary focus of the delivery. But where customer acquisition, operational analytics, or direct decision-making by the client's own staff are involved, a dashboard that can flexibly switch segments, adjust workflows, and surface results often matters a great deal.
This piece started from a version of the same question: should AI present its output in language and formats the customer already knows well? That question deserves real weight — information nobody can use, however accurate, never makes it into real work. But push on it a little further, and a different picture emerges. Interface and presentation shape how people understand and use what AI produces. The deeper problem in human-AI collaboration is whether AI understands what task it's actually part of.
The same question can be routine, or it can mark a turn in the task. The same answer, delivered at a different moment or against a different backdrop, can lead to entirely different consequences. AI needs to recognize when the task state has shifted, understand the goal it's currently serving, and know how to act on what comes next.
That kind of understanding — of a vertical domain and its specific operational contexts — does not emerge from the model on its own. It comes from technical teams and domain experts repeatedly deconstructing real cases together, turning the signals, context, responses, and risks scattered across professional experience into something a system can recognize, act on, and verify.
Right now, most AI projects ask domain experts to verify whether answers are correct — whether a particular line should have been said or whether a number is accurate. That understates the value they bring. What they really contribute is task understanding and professional judgment: how a task shifts, when intervention is needed, what form that intervention should take, and which outcomes cannot be assessed through short-term metrics alone. The technical team must then decompose that expertise and encode it at the appropriate layers of the system — the system prompt, context, rules, workflows, permission boundaries, and the broader mechanisms governing human–AI interaction.
Human-AI collaboration, then, is a task-centered partnership. People define the goals, constraints, and accountability, and ultimately own the outcome; AI participates in analysis, inquiry, judgment, and action. Organizations then refine both the division of labor and the system design in response to real-world results.
For an AI company, this is also the real barrier to going deep in any vertical. General-purpose models and technical tools are becoming widely available, but the domain expertise built on a single deployment doesn't turn into scalable capability on its own. That experience becomes scalable only when an AI company can continually translate domain expertise into task states, system mechanisms, and a functioning validation loop. Only then can a single success be reliably reproduced across more clients and more scenarios.
Getting the answer right only proves the model understood the question in front of it. Catching a shift in the task the moment it happens, understanding what comes next, and knowing when to answer, ask, stop, or hand the task back to a person — that's when AI starts doing the job.
Get Involved
Our authors are what set Insurance Thought Leadership apart.
|
Partner with us
We’d love to talk to you about how we can improve your marketing ROI.
|
David Lien is a partner at Lingxi (Beijing) Technology.
He wrote “Decoding New Insurance” (2020), which ranked among JD.com’s top books. Lien has held leadership roles at Sino-US MetLife, Sunshine Insurance and Prudential Taiwan, leading digital transformations and multi-channel marketing. A 2018 e27 Asia New Startup Taiwan Top 100 nominee, he holds a patent for the "Intelligent Insurance Financial Management System."
Viral TikTok hype around infinite banking is creating oversold life insurance policies, early lapses, and a growing consumer trust problem.
Search "infinite banking" on TikTok and you will find millions of views promising that a life insurance policy can make you your own bank, beat the market, and cut the banks out of your life. Most of it is sold by people who do not fully understand the product, to people who cannot sustain it. That is not a marketing win for our industry. It is a consumer protection problem, and it is ours to fix before someone less friendly fixes it for us.
I say this as someone who believes in the underlying strategy. A properly designed whole life policy, funded for high cash value and used as a private financing tool, is a legitimate thing with a century of regulation behind it. The concept is real. The selling is the problem.
I spent 30 years building sales teams and marketing organizations before I became a licensed agent, so I understand exactly why this trend spreads. The hooks are perfect. "Be your own bank." "Tax free." "The banks don't want you to know this." The mechanics are complicated enough that a confident voice with a whiteboard can fill the vacuum with whatever they want. Complexity plus a good hook is how misinformation travels in any category. Ours just happens to involve people's life savings.
Here is what I see on the front line, after the video ends. Policies funded far below what the strategy actually requires. Clients who expected to borrow from themselves in year two and did not understand that the early years are the slow years. And the worst outcome of all, the early lapse, where someone overcommits, cannot keep up the premium, and walks away having lost money on a product that only works with patience. They do not walk away thinking they were oversold one policy. They walk away distrusting permanent insurance, agents, and the whole industry.
That is the part the boardroom underestimates. Every oversold infinite banking policy that lapses does not just cost one client. It creates one more person who tells their friends that whole life is a scam, one more complaint that catches a regulator's eye, and one more reason the public discounts everything we say about cash value. The hype feels like free marketing for permanent insurance. It is the opposite. It is a slow tax on the credibility of the entire category.
We cannot regulate social media, and we should not want to. But we are not helpless either. A few things would actually move this.
First, out-educate the hype. The reason bad information dominates these searches is that we have largely ceded the ground. Honest, plain-English content that explains how the strategy really works, who it fits, what it costs, and who should not touch it, can rank and circulate in the same places the hype lives. If the first honest voice a curious person hears is ours, we win the relationship and we prevent the bad sale.
Second, set expectations before the application, not after the complaint. The break-even timeline, the fees, the funding discipline, and an honest "this may not be for you" belong in the first conversation. A client who understands the slow years does not lapse in year three. Underwriting protects the carrier. Expectation setting protects the client, and it protects us.
Third, name the misrepresentation. The claim that any whole life policy is an infinite banking vehicle is simply false, and it is doing damage under our own roof. The strategy requires a policy engineered for early cash value while staying inside the tax limits. When we let the label get attached to products that were not built for it, we validate the confusion. The industry polices a lot of things. This one is worth adding to the list.
None of this requires new products or new rules. It requires the honest story to be told louder than the hype, by the people who actually understand it. The strategy is legitimate. The trend is not going away. The only real question is whether the loudest voice on it will be a marketer who does not understand the product, or an industry that finally decided to show up.
Get Involved
Our authors are what set Insurance Thought Leadership apart.
|
Partner with us
We’d love to talk to you about how we can improve your marketing ROI.
|
Joseph McDermott is a licensed life insurance agent in 27 states and founder of Sovereign Life Group.
AI has surged to the second-biggest perceived business risk globally, yet actual insurance losses remain surprisingly low—for now.
Artificial intelligence (AI) has rapidly become one of the most important global business topics and risks. This is clearly reflected in the Allianz Risk Barometer, where AI rose from 10th place worldwide in 2025 to 2nd place in 2026 – the largest increase of any risk category. Across regions, AI now ranks among the most relevant risks, highlighting the speed at which it has moved up the corporate risk agenda.
From a claims perspective, however, the current loss situation appears relatively calm. The number of clearly confirmed AI-related losses remains limited, and if assessed purely on today's claims data, AI would not yet rank among the most significant loss drivers. This apparent gap between perceived risk and actual losses requires closer attention.
A large "grey area" exists in which AI involvement is difficult, if not impossible, to prove. In many incidents – whether cyber-attacks, business decisions or operational failures – AI is likely to play a role, even though it cannot be conclusively identified. As a result, current claims data may underestimate the true level of underlying risk.
What is already evident is that AI-related exposures are emerging across multiple lines of business simultaneously, but in very different forms. In cyber, AI is increasingly assumed to be used in areas such as phishing or malware development, even if its involvement cannot always be verified. At the same time, intellectual property disputes related to the training of large language models are gaining prominence, alongside data protection issues where AI is deployed without sufficient safeguards.
In liability insurance, risks are particularly relevant in connection with autonomous systems and AI-supported decision-making. One of the most visible areas currently is directors & officers insurance, where so-called "AI washing" – the overstatement or misrepresentation of AI capabilities – is already leading to claims. In addition, AI is significantly enhancing the effectiveness of fraud schemes, from business email compromise to advanced social engineering and voice-based attacks.
AI is not a risk that is limited solely to certain business areas and applications. It is emerging across many insurance products simultaneously – often not as the direct cause, but as an aggravating factor.
Looking ahead, there are strong indications that AI-related losses will increase substantially. AI acts as a powerful risk accelerator, with the number of incidents and related litigation rising globally. External observations point to a clear upward trend.
What sets AI apart from many traditional risks is its probabilistic nature. Errors are not exceptions but an inherent feature of the technology, even when systems are properly designed and implemented.
When such systems are deployed at scale and embedded into everyday processes, even a small error rate can translate into a significant number of incidents within a short period of time. Combined with the speed of deployment, evolving governance frameworks and the widespread use of AI tools across organizations, this creates a risk environment in which losses can escalate rapidly once they begin to materialize.
AI fundamentally changes how risk behaves. Unexpected output and errors are not an exception; they are inevitable. When not addressed and managed properly, even small deviations can lead to significant losses quickly.
At its core, AI risk operates on several levels. One lies within the technology itself. AI systems often generate outputs with a high degree of apparent confidence while remaining sensitive to small changes in input and prone to various forms of bias. This can have significant implications in areas such as decision-making, risk assessment or negotiation.
A second level arises from the way AI is implemented within organizations. While experience with AI continues to grow, many companies are still developing the necessary governance, controls and expertise, often under considerable pressure to adopt the technology quickly. Even under responsible use, the probabilistic nature of AI means that errors cannot be fully eliminated.
A third level relates to indirect effects. In many cases, AI is not the direct cause of damage, but rather a force multiplier that enhances existing risks by making attacks more convincing and fraud more effective.
Against this backdrop, it becomes clear that AI risk is not purely a technological issue. It is a business, governance and leadership challenge that requires a holistic approach. The fact that losses remain comparatively low today should not lead to complacency. Historically, losses tend to lag behind adoption – but once they emerge, they can develop quickly and at scale.
Effective risk management therefore starts with a clear understanding of the fundamental characteristics of AI and their translation into concrete business risks. Organizations need to make deliberate decisions about which risks can be mitigated, which can be accepted, and which should be transferred. At the same time, the opportunities offered by AI remain significant. Realizing these opportunities sustainably depends on addressing risks in a transparent and proactive manner.
AI offers enormous opportunities, but those opportunities can only be realized sustainably if risks are understood, addressed early and managed proactively.
As AI continues to be embedded more deeply into business operations, its effect on the risk landscape is expected to grow further. What is observable today is still only an early stage of a broader transformation – one in which the true scale of AI-related risk will become more visible over time.
Get Involved
Our authors are what set Insurance Thought Leadership apart.
|
Partner with us
We’d love to talk to you about how we can improve your marketing ROI.
|
Michael Daum is global head of cyber claims for Allianz Commercial.
Side underride crashes kill 300 annually, yet the trucking industry still resists guards that juries now value in multimillion-dollar verdicts.
My son Riley burned to death pinned inside his Honda Civic in a side underride crash in 2015. His death was part of a documented crash pattern that the trucking industry and federal regulators have studied, debated, and ignored since the 1960s.
Side underride crashes happen when a passenger vehicle, cyclist, pedestrian, or motorcyclist goes under the side of a semitrailer. The consequences are often devastating because the trailer frame bypasses the vehicle's safety systems and strikes the occupant space directly. Riley's collision occurred at a shallow angle and a relative speed of about 14.5 mph, lower than speeds at which tested side-guard designs had prevented underride.
The litigation that followed showed how a fatal truck crash can affect the entire transportation chain. The truck driver's insurer and motor carrier settled early. A motor carrier that had served as an unlicensed broker settled after a few months of discovery. The lawsuit against Utility Trailer Manufacturing, a major refrigerated-trailer manufacturer, went to a jury.
Riley's crash was one of roughly 300 deaths and 400 serious injuries that side underride causes each year, with an estimated societal cost of $7.4 billion. In 2023, 5,472 people were killed in crashes involving large trucks, about 30% more than a decade earlier. Seventy percent of those killed were occupants of other vehicles; another 12% were pedestrians, cyclists, or other nonoccupants.
Mistakes happen. Side underride guards, like seat belts and airbags, reduce the severity of consequences regardless of fault.
NHTSA has denied four formal petitions seeking side guards on semitrailers since 1979. The 1979 denial (FR 44:55077-55078) closed with: "If the evidence gathered by the agency indicates that side underride rulemaking could contribute significantly to safety, the agency will commence rulemaking."
The trucking industry's cost objection over whether to require side underride guards on semitrailers has a long history but a thin evidentiary base. In 1969, the industry's trade association told federal regulators that side underride "is not a hazard that warrants some kind of regulatory remedial action."
In 1991, NHTSA declared without evidence that side underride guards were not cost-effective. A 2021 Freedom of Information Act request confirmed the agency held no data or analysis to support that assertion. The industry clings to the same claim in regulatory comments and litigation: guards would be too expensive, add weight, and increase fuel use. Juries are unconvinced.
I tested those assertions.
In my 2026 peer-reviewed cost-benefit analysis, side underride guards produced positive net economic benefits under every modeled scenario, ranging from roughly $137 million to $2.8 billion.
The break-even threshold in my analysis is that modest: guards need to prevent as few as 24 deaths and serious injuries per year to be economically justified. The analysis also excluded litigation, settlements, defense costs, and insurance losses. A side guard with an aerodynamic skirt costs approximately $2,500 per trailer.
For insurers and fleets that bear the litigation costs, the actual break-even is lower still.
Discovery in Riley's case showed that Utility Trailer had known for decades that side underride was a serious hazard but had not designed, built, or tested its own side guard before the lawsuit. The company criticized the Angelwing, a side guard that an independent inventor had already designed, built, and crash-tested without the engineering resources of a major manufacturer, and made no attempt to develop its own solution. Two years before the verdict, IIHS independently crash-tested a side guard at 40 mph and confirmed it prevented underride. Wabash National successfully crash-tested its own design the same year. The jury found Utility negligent and returned an $18.9 million verdict. After the verdict, Utility publicly maintained that it had not negligently designed its semitrailers and argued that side guards would make them more dangerous.
Then, after arguing at trial that side underride guards were impractical, Utility developed and patented one. The company now offers a Side Impact Guard, describing it on its website as evidence of a "long-standing commitment to the safety of every motorist sharing the roadway" and claiming its innovations "set the gold standard for performance and reliability." As of 2026, Utility has delivered nearly 70 semitrailers factory-equipped with the guard.
The technology was never the obstacle.
Nearly every major semitrailer manufacturer now holds a side guard patent. The impracticality argument was an industry position, one the industry's own trade association funded specifically to develop defense strategies against side underride lawsuits, with manufacturers suppressing information from the public under a joint defense agreement.
The Utility verdict was not a one-off. Vehicle side underride cases have produced $32.5 million in Georgia for a fatality, $26.1 million in Iowa for a debilitating injury, and $13 million in a second Georgia case. Pedestrian and cyclist cases have produced an $81 million verdict in Utah, $11.5 million in Virginia for a bicyclist, and $8.5 million in New Hampshire for a bicyclist fatality, among others. Many more cases resolve confidentially. These are the hidden costs the industry never mentions when it argues against requiring guards.
The pattern is consistent. When side underride is not addressed before a crash, the costs appear afterward in verdicts, settlements, defense expenses, and rising insurance premiums. The math does not favor waiting.
Those verdicts trace back to a specific, identified crash mechanism with a documented fix. Side underride is not an anomaly. It follows from a design decision, the absence of a guard, that is identifiable, verifiable, and correctable. Insurers are not pricing it as one. Commercial auto insurance has posted 14 consecutive years of underwriting losses. Raising rates does not fix that. Preventing fatal and serious injury from the collisions that generate the claims does.
Fleets already get underwriting scrutiny for driver safety programs, telematics, dash cameras, maintenance practices, and loss history. Side underride protection is a documented liability exposure that belongs in that same conversation.
Insurers are not encouraging side guard adoption. They should be, through underwriting questions, premium credits, or better retention terms.
Testifying before the Senate Commerce Committee, the American Trucking Associations asked Congress in June 2026 to preempt state tort liability for vehicles that meet federal safety standards, while opposing the side guard mandate that would create the standard preemption requires. The industry wants the litigation exposure eliminated, but opposes the only mechanism that would justify the change. In the meantime, fleets and their insurers absorb the verdicts.
None of this requires waiting for an NHTSA side guard rule. Regulation is not a prerequisite for action.
The Supreme Court recently underscored a related point in a freight-broker liability case, Montgomery v. Caribe Transport II (2026). The unanimous decision recognized that common-law duties and standards of care are part of state safety authority. Justice Kavanaugh wrote that "truck safety is a matter of life and death," and that "Not all truck accidents can be prevented. But some can." He also acknowledged that litigation and insurance costs can be significant even when brokers prevail. The lesson is broader: truck safety decisions become liability decisions.
The question for fleets, insurers, brokers, shippers, and manufacturers is not whether federal regulations will eventually require side guards. It is why the industry keeps defending inaction in court instead of addressing a known hazard. The verdicts have been answering that for years, and the amounts keep adding up.
Get Involved
Our authors are what set Insurance Thought Leadership apart.
|
Partner with us
We’d love to talk to you about how we can improve your marketing ROI.
|
Eric Hein is a retired U.S. Fish and Wildlife Service policy analyst, a board member of the Institute for Safer Trucking, and the author of a peer-reviewed cost-benefit analysis of side underride guards for new semitrailers in the U.S.
His son Riley was killed in a side underride crash in 2015. Their story is featured in the ProPublica/Frontline documentary America's Dangerous Trucks.
Insurers must move beyond explaining AI outputs to documenting the full workflow, controls and human decisions behind each action.
Explainability has become one of the most familiar promises in responsible AI. It is easy to understand why. In insurance, a customer, regulator, underwriter or claims leader may need to know why an AI system recommended a price, flagged a claim, routed a case or generated a communication. A black-box answer is difficult to trust and even harder to defend.
But explainability solves only part of the governance problem. A human-readable rationale may describe why a system produced an output. It does not necessarily prove which data was used, which version of the model or prompt was active, which tools were called, which controls passed or failed, who intervened, or what action the organization ultimately took.
That distinction matters more in 2026 because insurers are moving beyond AI that simply summarizes or recommends. AI is increasingly embedded in workflows that retrieve documents, update records, route cases, generate customer-facing material and initiate downstream actions. Once AI participates in execution, governance must cover the entire path from input to outcome, not only the explanation attached to one answer.
Consider a seemingly straightforward AI-assisted decision. The system explains that it routed a claim for additional review because the submitted information did not match the policy record. That explanation may be useful, but it leaves critical questions unanswered. Which policy version did the system consult? What source document was treated as authoritative? Was the mismatch material or merely a formatting difference? Did a business rule confirm the finding? Did a human reviewer accept, correct or override it? Was the customer notified, and was the notification based on the final reviewed result or the original AI output?
An explanation addresses interpretation. Governance requires proof.
The difference is especially important when an issue surfaces weeks or months later. The people who designed the workflow may no longer remember the specific case. The model may have been updated. The prompt, knowledge source or decision rule may have changed. A screenshot of the final output cannot reconstruct the process that produced it.
Insurers therefore need a durable reconstruction record: a connected set of evidence that allows an authorized reviewer to replay the material steps of an AI-assisted workflow. This is not a demand to store every hidden technical detail or every piece of sensitive data forever. It is a demand to preserve the business-relevant facts necessary to understand and defend the decision.
The regulatory direction is already moving toward this broader standard. The NAIC Model Bulletin on the Use of Artificial Intelligence Systems by Insurers emphasizes written governance programs, lifecycle controls, documentation, accountability, and information that regulators may request during an examination or investigation. In 2026, the NAIC AI Systems Evaluation Tool pilot expanded that focus by helping regulators gather information about how insurers use AI, how they govern and mitigate risk, which models may be high risk, and what data those systems use. The pilot involves 12 states.
The same distinction appears in international guidance. The OECD AI Principles treat transparency and explainability as separate from accountability. Accountability includes traceability across datasets, processes and decisions throughout the AI lifecycle. The NIST Generative AI Profile similarly points organizations toward provenance, logging, monitoring, change management, overrides and incident handling. ISO/IEC 42001 frames AI governance as an organization-wide management system rather than a model feature.
None of these frameworks says explainability is unimportant. They show that explanation is one control within a larger operating system of governance. For insurance leaders, the practical message is clear: a well-written rationale cannot substitute for evidence that the workflow was properly controlled.
A reconstruction record should answer the questions that arise when an AI-assisted outcome is challenged. At a minimum, it should establish the business purpose and risk level of the use case; the identity and version of the model, agent, prompt or policy configuration; the authoritative inputs and sources used; the material steps, rules and tools invoked; the validation or guardrail results; the human approvals, edits, exceptions or overrides; the downstream action taken; and any later correction, complaint or incident linked to the case.
The record does not need to be one giant log file. In a mature enterprise, the evidence will often be distributed across workflow systems, model monitoring platforms, case-management tools, approval services and audit repositories. What matters is whether those pieces share reliable identifiers and can be assembled into a coherent timeline.
That timeline should be understandable to more than the engineering team. A compliance officer should be able to see what control failed. An operations leader should be able to identify where the case was held or released. An auditor should be able to verify who had authority to approve an exception. A customer-facing team should be able to explain the organization's final action without pretending that the AI made the business decision on its own.
The answer is not to capture everything indiscriminately. Excessive logging can create privacy, security, retention, and discovery risks. It can also bury the evidence that matters under millions of low-value technical events.
The better approach is risk-tiered evidence. A low-risk drafting assistant may require basic usage records and quality monitoring. A system that influences underwriting, claims, policy servicing or customer communications should preserve a far richer record. The higher the impact of the action, the stronger the requirements for source provenance, approval, segregation of duties, override justification and post-decision monitoring.
Insurers should also separate observability from authority. A system can be perfectly observable and still be allowed to do too much. Knowing that an agent called an external tool is not the same as controlling whether it was permitted to make that call. Evidence should therefore sit beside enforceable boundaries: approved tools, role-based permissions, transaction limits, release gates, escalation paths and the ability to stop or reverse an action.
"Human in the loop" is often presented as the answer to AI risk, but the phrase is too vague to function as a control. It does not identify which human, at what point, reviewing what evidence, under which threshold, with what authority.
Meaningful human oversight should be designed around decisions and exceptions. Routine, low-risk cases may pass automatically when predefined checks succeed. Higher-risk cases should pause for a qualified reviewer. Overrides should require a reason and, when appropriate, a second approval. Material changes to models, prompts, data sources or connected tools should trigger renewed testing rather than quietly entering production.
This design is more scalable than asking employees to reread every AI output. It concentrates human attention where judgment is needed and produces evidence that oversight actually occurred.
Insurance executives do not need to inspect raw model traces, but they should expect clear answers to five questions:
Can we identify every material AI-assisted workflow in production?
Can we reconstruct a disputed decision from source to final action?
Can we show which controls ran and who approved of any exception?
Can we distinguish a model recommendation from an action taken by the company?
Can we do all of this without exposing more customer data than necessary?
If the answer to any of these questions is no, the governance gap is not explainability. It is operational accountability.
The insurance industry should continue investing in explainability. Customers deserve meaningful information, employees need to understand system limitations, and regulated decisions should never be hidden behind technical complexity.
But the standard must now be higher. An insurer should be able to show not only why an AI system produced a recommendation, but what evidence it relied on, what controls constrained it, who exercised judgment and what the organization did next.
That is the difference between AI that sounds responsible and AI that can be governed in practice. Explainability helps people understand an answer. A reconstruction record helps the institution defend the entire decision.
Get Involved
Our authors are what set Insurance Thought Leadership apart.
|
Partner with us
We’d love to talk to you about how we can improve your marketing ROI.
|
Bhargavi Vepuri is a director in the insurtech and fintech field and an independent researcher with more than 10 years of experience in enterprise technology, AI-driven systems and cloud architecture.
She holds a master’s degree in computer science from the University of Missouri-Kansas City and is currently pursuing a second master’s degree in artificial intelligence and an executive MBA at the University of Texas at Dallas.
She is also an author, speaker, peer reviewer and technology community contributor.
The flash floods that brought New York City to a standstill were another stark reminder that it is no longer enough to simply predict extreme weather.
On July 18, 2026, New York City experienced another severe flash flood. In just a few hours, intense rainfall overwhelmed transport networks, forced ground stops at JFK, LaGuardia, and Newark airports, flooded subway stations, closed major roads, and disrupted countless businesses. For one of the world's largest financial centers, the effect was devastating.
In Previsico's New York Flash Flood report, we included a reconstruction of the event, which estimated economic damage of between US$200 million and US$610 million, with US$70 million to US$214 million potentially preventable through earlier, more actionable warnings.
For insurers, brokers, risk managers, and infrastructure operators, the event offers several crucial lessons. Perhaps the biggest of these is that while weather forecasting continues to improve, understanding precisely where flooding will occur, and acting on that intelligence, is now the real competitive advantage.
The NYC rainfall itself was remarkable, but the operational consequences were what made headlines in the US.
Within a matter of hours, subway stations filled with water, motorists required rescue, major highways closed, and all three of New York's principal airports suspended flights. Cultural venues also suffered cancellations, leaving thousands stranded across the city.
For organizations, these aren't simply meteorological incidents. They become business continuity events affecting employees, customers, supply chains, logistics, service delivery, and revenue.
Events like these are leaving organizations increasingly worried about their security, with uncertainty over which of their sites will flood next, when, and what they can do about it.
While traditional flood warnings remain an important public safety tool, their breadth means that the insights are often not actionable.
During the July event, the National Weather Service issued warnings covering entire counties across Kings and Queens (an area exceeding 170 square miles). Those alerts correctly identified the threat but could not distinguish which roads, buildings or transport assets would actually experience flooding.
Previsico's flood intelligence reconstructed the event at site level, forecasting approximately 68 square miles of flooding across the Northeast Corridor, with 37 square miles concentrated within the NYC metro core, identifying expected water depths as well as locations.
At a time when every minute of downtime carries financial consequences, this level of insight is far more valuable than broad awareness. For example, knowing a particular distribution center will see 20 inches of floodwater by mid-afternoon gives people crucial time to relocate stock, move vehicles, protect equipment, and activate contingency plans before disruption occurs.
Perhaps the most compelling insight from the report concerns preventability.
Previsico estimates that between US$70 million and US$214 million of damage from the July event could potentially have been avoided through earlier, site-specific warning combined with operational action.
This moves flood forecasting beyond risk assessment into risk reduction. Historically, insurers have concentrated on pricing flood exposure and settling claims afterwards. Increasingly, technology allows the industry to intervene before losses occur.
Moving vehicles out of underground car parks, temporarily shutting vulnerable facilities, protecting critical equipment or delaying deliveries by a few hours may dramatically reduce ultimate claims costs.
One interesting finding from the July storm is that rainfall did not need to reach record-breaking levels to generate significant disruption.
Peak hourly rainfall reached 2.04 inches per hour. This is well below Hurricane Ida's 3.15 inches per hour in 2021, but still exceeded New York City's sewer design capacity of approximately 1.75 inches per hour.
That relatively small difference matters enormously. Urban flooding is often driven less by total rainfall than by the point at which drainage systems become overwhelmed. Once that threshold is crossed, relatively modest increases in rainfall can produce disproportionately large increases in disruption.
For insurers, this reinforces the importance of understanding infrastructure vulnerability alongside traditional catastrophe modelling.
Climate change is undoubtedly increasing the frequency of intense rainfall events across many parts of the world. Yet adaptation cannot rely solely on larger drainage systems or more resilient infrastructure; operational resilience must become equally important.
This requires a combination of live rainfall data, hydrodynamic modeling, and probabilistic forecasting capable of extending warning times beyond conventional alerts. As a result, businesses can get sufficient notice to make practical decisions before water arrives, transport operators can identify which assets require intervention, and emergency planners can prioritize resources where flooding is genuinely expected rather than across entire administrative regions.
Events such as these reveal a 'new normal'. Extreme rainfall is no longer exceptional enough to be treated solely as an emergency response issue. Instead, it has become an operational business risk demanding continuous monitoring and proactive management.
This requires moving beyond traditional weather warnings towards location-specific intelligence that identifies exactly where flooding will happen, how severe it is likely to become, and how much time organizations have to act. As flash flooding becomes more frequent, the competitive advantage for insurers will lie not only in understanding risk, but in helping customers prevent losses before they occur.
That shift, from paying claims to enabling resilience, may prove to be one of the industry's biggest opportunities, both in supporting its clients, but also improving its bottom-line.
Get Involved
Our authors are what set Insurance Thought Leadership apart.
|
Partner with us
We’d love to talk to you about how we can improve your marketing ROI.
|
Jonathan Jackson is CEO at Previsico.
He has built three businesses to valuations totaling £40 million in the technology and telecom sector, including launching the U.K.’s longest-running B2B internet business.
Property and casualty insurers that analyze testimony at scale will price risk more accurately than competitors relying on instinct alone.
Every property and casualty claim hinges on testimony. Not documents, though documents matter, and not data fields in a claims system, though those matter, too. What moves a claim from first notice of loss to final resolution is what people say under oath and on the record.
How well we create and manage testimony is often the difference between a good outcome and a poor one—a fairly resolved claim or an overpaid claim. This includes the insured's recorded statement, an examination under oath, the treating physician's account of causation, the accident reconstructionist's opinion, and the corporate representative's answers in a bad-faith suit.
Testimony—the oral record—is the currency we use to analyze risk and construct the narratives that support our positions. Reserves are set on it. Settlements are priced against it. Juries decide on it. When a claims organization is good at its work, it understands, dissects, connects, and redeploys testimony. When it is not, it overpays, settles cases it should have tried, and tries cases it should have settled.
If testimony is the currency, most claims organizations are managing their finances by hand, using an abacus. A deposition is taken, read once by assigned defense counsel, and summarized in a report that lands in a claim file, then effectively disappears. The knowledge inside it—how a particular plaintiff's expert testifies about future medical care, which questions or contradictions unsettle a professional expert, and how a repeat-player plaintiff firm builds its damages case—is gathered once and then thrown away. The organization paid for the transcript and the hidden data it contains. Yet almost none of that value is used beyond the single matter that produced it.
One of us argued in a prior piece, "Moneyballing Litigation," that litigation teams still select witnesses and lawyers on gut impression, much as baseball general managers once selected players based on how they looked in a uniform rather than on objective data. That argument holds for claims, as well. The vast trove of deposition data that could inform claims decisions remains largely unmined. This article extends that assertion.
To be fair, this kind of data mining was impossible not long ago. Nobody could read across 10 years of transcripts from every case a carrier had handled, pull out every instance of a given expert opining on lumbar disc herniation, and compare those instances for consistency. The labor was prohibitive.
Today, however, we have moved from manual human review as the only option to machine-first processing and analytics as a true capability. This expands both what we can understand and what we can do with the most important currency we manage—testimony. The emerging field of testimony analytics is creating opportunities for insurers to capture both efficiencies and strategic advantages. Organizations that learn to analyze that medium at scale will price claims and risk more accurately than those that do not. Let's look at how.
Testimony analytics creates value at two levels: the individual case and the broader portfolio. Both levels produce efficiencies, but the portfolio level also unlocks strategic advantages unavailable within a single case.
The first level is the individual case. Obtaining, reviewing, and analyzing testimony consumes an extraordinary amount of billable attorney time. Yet much of that work still relies on tools and methods that have changed little in decades. AI and testimony analytics reduce that burden by helping counsel search and summarize transcripts, identify admissions, and compare testimony with medical records and other evidence. For claims organizations embracing AI, tasks that once required hours of billable time can now be completed in minutes, producing faster turnaround and lower attorney fees. Most industry attention remains focused on efficiencies at this level because the savings are both conspicuous and tangible.
The larger opportunity lies at the portfolio level: leveraging aggregate data. By treating all of an organization's testimony as a single, queryable body of knowledge, transcripts become more than case files—they become institutional memory. Across matters, they record the statements, strategies, and behaviors of insureds, company witnesses, retained experts, opposing experts, defense counsel, and adverse attorneys.
By extracting and leveraging that aggregate history, a claims organization can identify patterns that no single case reveals. It can better prepare witnesses, evaluate repeat experts, profile recurring firms and attorneys, detect anomalies and contradictions across claims, and improve outcomes across its portfolio. By mining information hidden in testimony, organizations can use previously ignored data not only to increase efficiency, but also to gain a strategic advantage through better-informed decisions and increasingly reliable predictions. In testimony, the past is often prologue.
It is now possible to turn testimony into a searchable body of institutional knowledge and use it to generate a wide range of analytics. As data is added, the value compounds: every new transcript strengthens the system, transforming testimony the organization has already paid for into a reusable data asset rather than dead weight in a file room. For a large insurer responding to a disaster, that could mean identifying recurring participants, uncovering potential fraud, avoiding improper payments, and recovering millions.
Claims organizations that build a portfolio-level testimony capability will out-execute those that do not, and the gap will widen rather than close.
Managing a claim well means optimizing the creation of testimony and then using it effectively—in motion practice, settlement negotiations, or before a jury. An organization that grounds its decisions in its accumulated testimony data can make a better-informed judgment.
An organization relying on the assigned adjuster's memory and the handling attorney's instinct is guessing. On one claim, the guess might beat the model. Across 5,000 claims, it will not. As in baseball, better information yields more wins on average, and claims is a business of averages.
A second, equally important reason to act is the meaningful risk that the plaintiff bar will deploy these capabilities at scale sooner. Plaintiff firms understand the power of technology and are using it to widen the intake funnel and increase case volume. Far more investment is flowing into plaintiff-side technologies than into defense-side technologies. The hundreds of millions of dollars invested across a growing group of plaintiff-side AI platforms illustrate the scale of that effort.
In the end, organizations that learn to manage and analyze testimony at scale will handle claims more efficiently, price risk more accurately, deploy better strategies, and improve outcomes across their portfolios.
"Moneyballing Litigation" imagined sealed envelopes containing hidden statistics about witnesses and attorneys. The data in those envelopes already existed; it was simply scattered across transcripts, matters, firms, and years. Testimony analytics makes it possible to open those envelopes at scale—to learn from every witness, expert, attorney, and firm an organization has encountered and apply that knowledge to every matter that follows. That is the opportunity now before claims leadership.
Get Involved
Our authors are what set Insurance Thought Leadership apart.
|
Partner with us
We’d love to talk to you about how we can improve your marketing ROI.
|
Taylor Smith is the founder and president of Suite 200 Solutions.
The firm provides advisory services and market intelligence to claim executives, defense attorneys, technology providers and private equity.
Michael Okerlund is CEO of Cloud Court and a former IP litigator and general counsel.
He focuses on how LegalTech and AI can leverage aggregate testimony and litigation data to generate strategic insights.
The question is: When is good enough good enough? The answer depends on whether you see AI as a math/science problem or as a legal/regulatory one.

When I taught my older daughter to drive, my (overly) nervous tendency to constantly kibitz caused her to blurt out: "You have to let me make my own mistakes."
As she drove my sportscar on a winding backroad with narrow lanes and no shoulder, and as she occasionally drifted toward the middle even though oncoming traffic could appear suddenly over a rise, I assured her that she was, in fact, not allowed to make any mistakes.
Yes, I would try to take a hands-off approach about school, friendships, soccer and so on. But driving? Nope. That was off-limits.
While I'm happy to report that, at age 32, she has never had an accident — not even a moving violation — the tension we worked through springs to mind as I think about the deployment of AI. There is a fundamental tension between having AI improve as fast as possible — to get as many benefits out to as many people as soon as can be done —and a legal system that will hold the AI accountable for each and every harm it causes, no matter if that loss is in the service of a long-term gain for society writ large.
The underlying tension between statistics and accountability goes even beyond the usual issues that accompany the rise of a revolutionary technology. So AI faces a hard question: When is good enough good enough?
Let's have a look.
The clearest example of the tension is probably in autonomous vehicles, where Tesla took the speed route while Google's Waymo took the careful one.
Tesla relies just on cameras and radar as the sensors in its AVs, largely because they are much less expensive than the Lidar that Waymo and others use, meaning that Tesla could deploy what it calls Full Self Driving (Supervised) quickly. (The "supervised" label refers to the fact that, while drivers are told they can trust their cars fully, they are legally required to stay alert and be able to take control of the car instantly.) CEO Elon Musk also encouraged aggressive use of the technology so he could gather as much data as possible on problems that needed to be ironed out before the cars could be fully autonomous.
The result is that Tesla's cars have logged nearly 13 billion miles in FSD mode — but also that there have been all sorts of complaints about problems with the software, as well as numerous accidents and even fatalities. Tesla has mostly avoided legal liability because of the fine print about drivers retaining responsibility for their vehicles even in FSD mode. Musk has said that problems are inevitable but that, in the long run, his rapid deployment of AI will reduce the total number of car accidents and fatalities.
While Musk has been promising that full autonomy was just around the corner for a decade, his vaunted fleet of robotaxis has logged just 380,000 paid miles without a safety driver in a car. He and his supporters still argue that his advantage in generating real-world data on driving, based on all the cameras and radar systems he has in the nearly 10 million Teslas on the road, will eventually make him the winner. But recent declines in the stock price for Tesla are being attributed to growing concern among his investors about his ability to deliver, after so many promises went nowhere. We'll see.
Meanwhile, Waymo took the go-slow approach, using a full array of sensors on the assumption that they would ride the exponential Moore's law cost curve and become inexpensive enough soon enough. Prices have, in fact, cut the cost of a Lidar from about $75,000 per vehicle to $7,500, and technologies are out there that could take the price down into the hundreds of dollars per car. Waymo has rolled out the cars cautiously enough that it only has about 4,000 robotaxis on the road, but they have logged 200 million paid, unsupervised miles — so more than 500 times Tesla's total. There have been glitches with Waymo, such as with misunderstanding signs warning of construction zones, but nothing like what Tesla has faced, so Waymo is the clear leader on AVs at this point.
Software developers take an approach like my daughter's: focusing on learning quickly even if the speed leads to some mistakes along the way. The legal system, however, takes my approach: Even if fast learning reduces the total number of lives lost and total damage that occurs over the lifetime of an AI, those who deploy it are liable for each and every mistake along the way.
Basically, the legal system says: Don't tell me that you constructed a model and optimized it for gains to society writ large. If an AI hurt my parent/child/friend, I demand accountability.
Prior authorization’s new reality: AI does the evidence work, a clinician owns the call, especially for denials.
Close to 53 million prior authorization requests hit Medicare Advantage plans in 2024. No honest reader of that number can believe the current prior authorization model can be run effectively by humans alone, and no serious operator would argue that it should be run by machines alone.
As more health insurers use AI to help manage the prior authorization process, more hospitals, doctors, and patients have cried foul. Yet the interesting question isn't whether AI belongs in prior authorization. Scale alone makes AI an operational necessity.
The better question to ask is how we divide that labor between AI and clinicians, keeping human expertise, judgment, and experience in the loop throughout the process. If AI can help deliver the right outcomes for patients, shouldn't it be part of the process?
I think the answer is this: within a couple of years, prior authorization in the United States will run on a settled split. AI does the evidence work at machine speed, quickly approving requests that meet payers' guidelines, and a board-certified clinician owns every denial. Many health insurers have begun touting this split, and those that haven't done so will fall behind on turnaround and overturn rates, to the detriment of the trust of the physicians whose patients they cover.
The AI half of that split isn't a policy debate. It's already happening.
The 2026 HealthEdge Annual Payer Report puts AI adoption among payers at 91%, with prior authorization and claims adjudication among the highest-impact deployment areas. And UnitedHealth Group, which operates the nation's biggest health insurer, has said it's investing $3 billion in AI in 2026-27 to automate more processes, including speeding prior authorization decisions.
New rules from the Centers for Medicare & Medicaid Services (CMS) on prior authorization timelines and the June 2025 insurer pledge, which saw the largest payers commit to real-time processing and standardized electronic prior authorization by 2027, have arguably contributed to that uptake. Amid tightening deadlines and a growing number of prior authorization requests, AI is increasingly emerging as the practical lever insurers are turning to meet those deadlines at scale.
What's important is that this AI adoption comes with protections. That means clinician oversight and expert judgment. The buck needs to stop with humans, especially when it comes to denials. Some health insurers have quietly been treating AI as a way to automate reviewers out of the loop rather than to equip them. That is the wrong build, and it's unlikely to survive the next regulatory cycle.
The underlying principle behind all this – the idea that "AI flags, a clinician affirms" – is already emerging as the floor in prior authorization. As of April this year, nine states have enacted laws on AI and prior authorization, and while each has its differences, the common thread between them is a requirement for human review of claim denials (KFF). I think we'll see that number continue to grow, even as the Trump administration pushes to preempt state AI legislation. The administration's own framework has drawn a line in the sand. It targets duplicative, innovation-blocking state rules, not the ones that protect consumers from fraud and harm.
The best play for health insurers now is to ensure they're ahead of the curve. CMS's new rules require payers to publicly report turnaround, denial, appeal, and overturn rates. Once those numbers are comparable across payers, any reviewer operating without AI-assisted evidence synthesis will be visibly, quantitatively below the standard set by those who have built for the split.
Those who are operating with AI but without clinician oversight risk falling into a similar trap. Speed without judgment is where prior auth goes wrong, and persistently high denial rates become a financial and reputational liability long before they become a compliance one.
The winning model is a settled division of labor. AI handles ingestion, timeline reconstruction, guideline matching, and first-pass evidence synthesis. The clinician makes the determination and carries accountability for it, in their name, on the record. Administrative AI runs the pipes, clinical AI supports the call, and humans remain in the loop where the loop matters.
For health insurance executives making build decisions this quarter, the tangible moves are straightforward. Fix the process, don't throw it out. Build explicitly for clinician accountability rather than around it. Invest in the neutral review layer instead of trying to litigate it away. And most importantly, do the right thing and be vocal about what you're doing. Transparency is non-negotiable.
Today, the question we hear most often is whether AI belongs in prior authorization. In the next couple of years, the question flips: Why was this contested decision not supported by AI-assisted evidence synthesis? The insurers who can answer that question with a straight face are the ones building for the split now.
Get Involved
Our authors are what set Insurance Thought Leadership apart.
|
Partner with us
We’d love to talk to you about how we can improve your marketing ROI.
|
Madhu Reddiboina is the founder and CEO of RediMinds, a healthtech firm specializing in AI-assisted contested medical review.