Download

How Are 2022 Strategic Initiatives Progressing?

Commercial insurers will continue to advance with their transformation strategies in 2022. However, their focus will look a little different than it did a year ago.

street

When the pandemic hit in 2020, many property and casualty commercial insurers had to pause, stabilize and reprioritize their digital transformation plans amid lower business volumes, economic lockdowns and an uncertain financial environment. But that all changed in 2021 as commercial insurers pressed the pedal to the metal. Now, a new study from SMA indicates that commercial insurers will continue to advance with their transformation strategies in 2022. However, their focus will look a little different than it did a year ago.

SMA's recent research report, "2022 Strategic Initiatives: P&C Commercial Lines," features market insights from an annual survey of insurance executives about the state of their strategic plans. Over the past two years, the insurance industry has shifted its priorities in response to changing consumer demands, altered business patterns and the workforce revolution. This year, 100% of commercial lines carriers are at some stage in their digital transformations. But, as insurers move past the plans implemented during COVID-19, many realize that they are not as far along in their transformations as they initially believed, and there is still a significant opportunity to transform their businesses. 

When looking at differences between insurers focused on small commercial versus mid/large commercial lines, there is significant variance in the business drivers pushing technology investments forward in 2022. In the small commercial segment, growing existing lines, markets and geographies is the number one driver this year. As insurtechs and new entrants increase market competition, small commercial insurers are more likely to focus on growth than their mid-market/large commercial peers. Increased competition is also why more than half of small commercial insurers are also focusing on cost containment.

See also: Climate Change and Product Liability

On the other hand, most mid-market/large commercial insurers are aiming for business optimization and transformation with their technology investments to reduce complex manual processes. Currently, there is a wealth of opportunity for them to automate operations and leverage insights for greater efficiency.

What is clear in 2022 is that commercial insurers seem to have solid road maps for their digital transformation, even if many are still in the early phases. As the year unfolds, technology investments will be necessary to build a platform for innovation and growth. Rethinking talent strategies will also be critical now that employees' expectations have forever changed due to the pandemic. A major change is underway, driven by key strategic initiatives evolving traditional and transformational aspects of the business, and insurers will need to be bold and embrace change to be successful in 2022 and beyond.

For more information on specific strategic initiatives of commercial lines insurers, including the strategies of the small commercial and mid/large markets, read SMA's recently published research report, "2022 Strategic Initiatives: P&C Commercial Lines."


Mark Breading

Profile picture for user MarkBreading

Mark Breading

Mark Breading is a partner at Strategy Meets Action, a Resource Pro company that helps insurers develop and validate their IT strategies and plans, better understand how their investments measure up in today's highly competitive environment and gain clarity on solution options and vendor selection.

The Importance of Algorithmic Fairness

Insurers have an opportunity to shape the discussion on algorithmic fairness by demonstrating awareness of potential societal implications.

algorithm

The discourse around algorithm fairness has garnered increasing attention throughout the insurance industry. As the use of machine learning has become more common, from marketing and underwriting to claims management, regulators and consumer rights organisations have raised questions about the ethical risks posed by such technology.

A catalyst of this social discourse was an article titled Machine Bias published by the investigative news organization ProPublica. The paper focused criticism on a law case management and decision support tool used in the U.S. judicial system called Correctional Offender Management Profiling for Alternative Sanctions, or COMPAS.

A conclusion of the academic research surrounding this debate is that there are competing definitions of fairness, and these definitions may be incompatible with one another. The concepts of fairness at the center of the discussion are calibration (a.k.a. predictive parity) and classification parity (a,k,a, error rate balance). There is also the concept of anti-classification, which calls for sensitive (a.k.a. protected) attributes not to be explicitly used in decision-making.

A stylized example, designed for educational purposes, illustrates the intrinsic incompatibility of predictive parity and error rate balance. The example uses the Adult dataset, which figures prominently in studies on machine learning. Gender is the sensitive attribute of choice. It is demonstrated that a classification model that satisfies predictive parity across two groups cannot satisfy error rate balance if the baseline rate of prevalence differs between the groups.

The dataset, which is publicly available, comprises 48,842 anonymized records of annual income and personal information (such as age, gender, years of education, etc.) extracted from the 1994 U.S. Census database. The prediction task is to determine whether a person makes more than $50,000 a year.

In the dataset, 24% of individuals are high earners. This baseline rate is higher for males (30%) than for females (11%). The dataset has been an object of research for its imbalance on gender, as females make up only 15% of high earners but 33% of the entire data set.

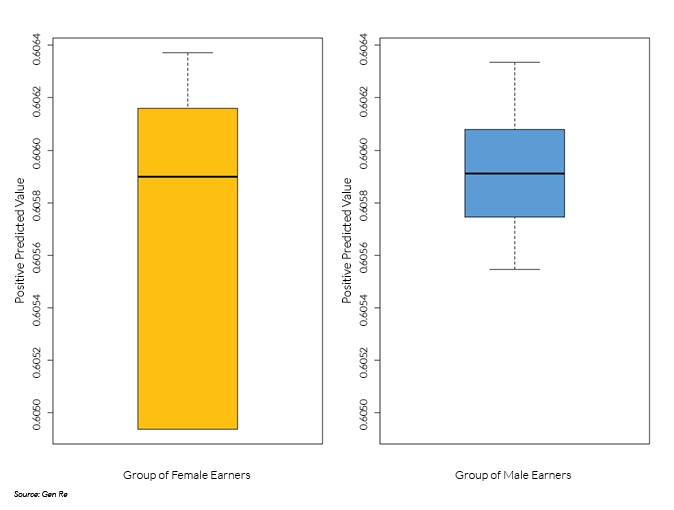
The algorithm satisfies predictive parity at a chosen threshold of predicted probability of being a high earner if in the category of predicted high earners the empirical probability of being a high earner is independent of group membership, where group membership is defined by the sensitive attribute. In plain English, the Positive Predictive Value (PPV), defined as the ratio of true positive count to the sum of true positive count and false positive count, must be equal across groups within an acceptable margin of statistical error. As shown in the box plot below, for a threshold of 32% of predicted probability of being a high earner, the (mean and median of the) PPV of the high-earner category equals 61% for both groups. In the box plot, the median is represented by a horizontal bar within the box, and the box marks the range between the first and third quartile.

Chart of groups of earners and positive predicted values

Turning to the concept of error rate balance, the algorithm satisfies this concept of fairness at a chosen threshold of predicted probability of being a high earner if the false positive and false negative error rates, respectively, are equal across groups. A direct consequence of a scoring model satisfying predictive parity is that it violates error rate balance if the baseline prevalence differs across groups. Thus, despite satisfying the concept of predictive parity, the algorithm has a disparate impact on the two groups.

See also: The Challenges of 'Data Wrangling'

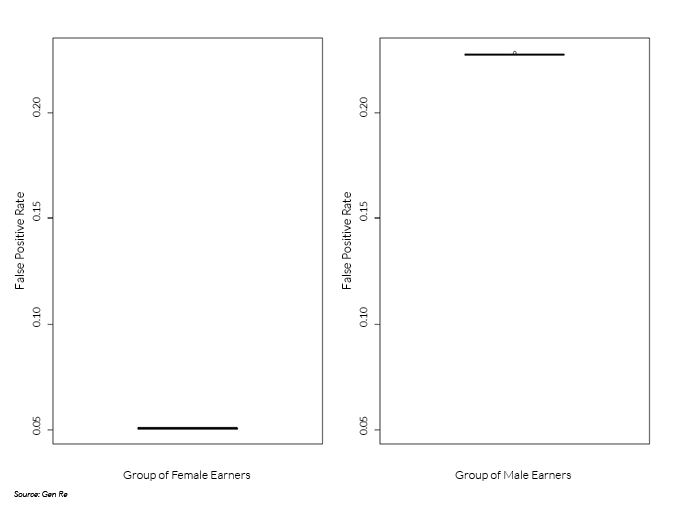
In the stylized example, the group of female earners has a lower rate of high income. Thus, in the presence of predictive parity, the group of female earners experiences a lower rate of false positives (see box plot below). Compared with a false positive rate of 23% for the group of male earners (median, displayed as horizontal bar within box in right panel), this rate equals 5.1% for the group of female earners (left panel).

Chart of group of earners and false positive rate

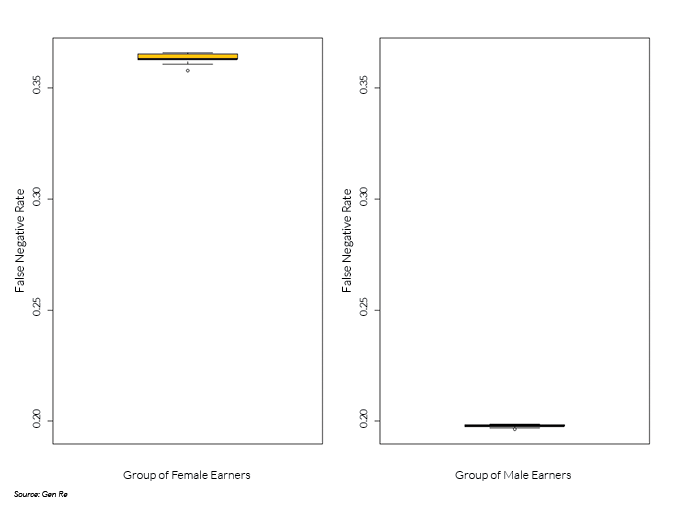
Correspondingly, the group of male earners experiences a lower rate of false negatives (see box plot below). Compared with a false negative rate of 36% for the group of female earners (median, displayed as horizontal bar within box in left panel), this rate equals 20% for the group of male earners (right panel).

Chart of groups of earners and false negative rate

In applying algorithms, it is important to recognize the trade-offs between different concepts of fairness and the presence of disparate impacts. Fairness is ultimately a societal, not a statistical concept. Insurers have an opportunity to shape the discussion on algorithmic fairness by demonstrating awareness of potential societal implications of their algorithmic decision-making.

This article first appeared at GenRe.com. 


Frank Schmid

Profile picture for user Frank Schmid

Frank Schmid

Frank Schmid is Gen Re’s chief technology officer.

He leads the IT department and hosts meetings in business data science to discuss research methodology in econometrics and machine learning. Previously, Schmid was affiliated with AIG, the National Council of Compensation Insurance and the Federal Reserve Bank of St. Louis.

He holds a doctorate in economics from Leuphana University of Lüneburg, Germany, where he held an appointment as an extraordinary professor of business administration. Schmid has also taught finance and economics at academic institutions in Europe and Asia-Pacific. In 2006, he received the Hicks-Tinbergen Award from the European Economic Association, jointly with Gary Gorton of Yale University.

Balance of Information Between Insurers, Consumers

Insurers are already familiar with adverse selection. Now, they are getting to grips with the new concept of inverse selection that arises with big data.

data

The widespread digitization of the economy has created a wealth of data on risk exposures for insurance companies. But how insurers exploit what has become known as big data has prompted widespread discussion around data ethics, especially in regard to transparency and fairness where consumer data is used to market and to price risk.

Insurers are already familiar with the concept of adverse selection. Now they are getting to grips with the new concept of inverse selection that arises with big data.

It’s useful to look at a basic risk spectrum to explore how big data can fundamentally change the information balance of insurers and insureds, and the latter’s perception of risk.

Usually, the consumer has private information about where s/he is located on the risk spectrum, exposing the insurer to the risk of adverse selection. Using big data combined with machine learning, the insurer might be able to uncover the location and eliminate the information asymmetry. Where the consumer’s risk perception is poorly calibrated, the insurer might be able to reverse the information asymmetry in its own favor by having a more precise read of the risk than the consumer has, and even determine the consumer’s perceived location.

With this reversal in information asymmetry in mind, how should the insurer price risk – on the basis of actual risk or the consumer’s perception of risk? And should the insurer make big data available to the consumer or to society?

Consider the basic consumer risk spectrum (see below). The insurer has a read of the average risk on this spectrum but doesn’t know the locations of the individual consumers. The consumers on the other hand know their locations.

Knowing only the average risk, the insurer prices the policy to the center of the spectrum. All higher-risk consumers will purchase insurance and all lower-risk consumers will not. In consequence, the insurer won’t break even. It’s a simple representation of adverse selection.

Chart 1

When the insurer is equipped with big data, this situation changes, however. The insurer now has granular consumer information, potentially observed at high frequency, and can gauge the consumers’ true locations on the risk spectrum – and differentiate premiums accordingly.

In this case, every consumer will purchase insurance. The lower-risk consumers now have access to insurance at premiums commensurate with their actual risks. The higher-risk consumers will purchase insurance also, albeit at higher premiums, no longer collecting an information rent. And the insurer will break even. Clearly, a socially desirable outcome.

See also: Why Exactly Does Big Data Matter?

What happens if the consumer’s perception of risk is not well-calibrated? Let’s look at consumers 4 and 8 (see below). Consumer 4 erroneously believes him/herself to be lower-risk, whereas consumer 8 errs in the opposite direction. If the insurer prices to the actual location on the risk spectrum, then consumer 4 will not purchase a policy; consumer 8 on the other hand will still purchase a policy, at a premium that s/he perceives as a bargain.

Inverse selection arises if the insurer sets the premium to the maximum of the actual risk and the consumer’s perceived risk. Then the insurer will collect an information rent on consumer 8.

Chart 2

If consumer 4 knew that s/he is higher risk, then s/he would purchase insurance at the quoted premium, and s/he would be better off. This situation of the consumer’s misperception of risk raises the question of whether the insurer should make its information available to the consumer.

Objectively, big data has the potential to broaden access to insurance by removing information asymmetry – the elimination of the consumer’s information rent comes at no loss to society.

However, there is the potential for shifting the information balance in favor of the insurer, which would allow the insurer to earn an information rent – the broader availability of insurance remains.

Consumers with poorly calibrated risk perception would benefit from having as equally a precise read of their risks as the insurer. That’s why some have called for making the insurers’ big data available to the consumer or, more generally, to society.

This article appeared originally at GenRe.com.


Frank Schmid

Profile picture for user Frank Schmid

Frank Schmid

Frank Schmid is Gen Re’s chief technology officer.

He leads the IT department and hosts meetings in business data science to discuss research methodology in econometrics and machine learning. Previously, Schmid was affiliated with AIG, the National Council of Compensation Insurance and the Federal Reserve Bank of St. Louis.

He holds a doctorate in economics from Leuphana University of Lüneburg, Germany, where he held an appointment as an extraordinary professor of business administration. Schmid has also taught finance and economics at academic institutions in Europe and Asia-Pacific. In 2006, he received the Hicks-Tinbergen Award from the European Economic Association, jointly with Gary Gorton of Yale University.

OCR Plus AI Opens New Vistas

AI-powered optical character recognition lets insurers unlock vast troves of data and streamline all processes.

artificial intelligence

Insurers still struggle with PDFs, images and handwritten documents. Countless human hours are required to manually extract the data into a machine-readable format. This process is known as ETL (extract, transform and load). Insurers that can maximize their ETL capabilities have a powerful competitive advantage. 

Enter optical character recognition, also known as text recognition. OCR, which converts text from scanned paper documents, photos, books and PDF files into a machine-readable format, isn’t new. What is new is coupling OCR with AI and machine-learning algorithms to reliably generate text that can be processed, indexed and retrieved. 

This technology can leverage existing data sets that comprise thousands of scanned documents and images already interpreted by humans. Smaller, manageable tasks are tackled first. AI and machine learning train and optimize algorithms, and over time the need for human intervention decreases in all departments.

Boosting Marketing and Sales

In employee benefits insurance, AI-enabled OCR can assist sales and underwriting teams by automatically extracting key details from RFPs and lengthy policy documents. It can automatically scrub RFP emails, multiple PDF documents, plan booklets and even scanned images of policy documents for key details. This data can then be loaded into the insurance company’s sales and underwriting systems, such as a quoting and rating engine, to create an initial “shell” quote in seconds.

Insurance companies typically have vast quantities of historical data in unstructured formats. You can call those vast quantities big data--or just an information goldmine!

AI-enhanced OCR can capture relevant data, enabling leaders to identify trends, make predictions and develop products in response to customer preferences.

Speeding Claims 

A quick, painless claims experience is key to maintaining customer loyalty and brand reputation. But you can’t sacrifice quality for speed. Insurers must have accurate data for claims processing to avoid overpayments, fraud and legal challenges and penalties.

OCR-enabled claims processing automation software can help speed claims with little or no human intervention without sacrificing quality. For example, clients can take a picture of the receipt from their dentist or car mechanic and send it to their insurer. OCR software can structure the data from the image of the receipt and confirm that the transaction is legitimate and process the claim–all without human intervention.

In 2016, Lemonade famously set a world record for the fastest-processed insurance claim. Their digital assistant, equipped with OCR, received a claim for a stolen $979 coat, checked the claim against the policy, ran 18 anti-fraud algorithms and made the payment in less than three seconds.

See also: Untapped Potential of Artificial Intelligence

Giving Customers a “Wow” Experience

Redundant data entry and drawn-out document-processing times contribute to a poor customer experience. McKinsey found that 30% to 40% of an underwriter’s time is spent on administrative tasks such as re-entering data or manually executing analyses. 

Today’s clients demand rapid turnaround for quotes, enrollment and claims. Insurers that fail to respond rapidly will lose clients.  

OCR reduces human errors and lets underwriters and other professionals focus on more valuable work. OCR also lets clients process their own documents, which can help insurers speed processes. 

Challenges and Best Practices

Like any emerging technology, AI-boosted OCR has limitations. Insurers should look to solutions that emphasize flexibility and configurability. Effective OCR applications can help insurers extract, transform and load text data and present it in any fashion they’d like, whether it’s tables, line items or any other format conducive to business needs.

Ineffective applications can result in losing time and money on technology that doesn’t work well.

Image quality is an important consideration. Thanks to machine learning, OCR applications can interpret more challenging data sources over time. To produce the best results, they should be fed a steady stream of high-quality image data with appropriate lighting, contrast and resolution. Camera applications that contain real-time image quality assessments can help users submit documents for clean processing.

OCR, like all AI-based technologies, requires continuing human inputs and oversight. The more data collected and verified by humans, the faster an OCR application will be trained. Transparency and explainability are always important when dealing with AI, and OCR applications must enable humans to easily understand AI-based outcomes and correct any problems.

See also: 20 Insurance Issues to Watch in 2022

How to Get Going

Insurers need OCR applications that are flexible, straightforward and customizable. But they don’t often have the required internal resources. As a result, many insurers are turning to industry partners with access to AI specialists, large data sets for training algorithms and cost-effective OCR services provided at scale. 

To take full advantage of OCR, insurers need modern sales, underwriting, policy processing and claims systems. Legacy systems can sharply limit the effectiveness of OCR and make integration costly.

Getting the most out of this emerging technology takes research and planning. But it’s becoming increasingly important to adopt it to stay competitive.

Breakthrough Technologies for 2022

The two most immediately relevant are "the end of passwords" (yay!) and the growing availability of "synthetic" data to train AI in situations where there isn't enough real data available.

Image
abstract technology

The MIT Technology Review's annual list of breakthrough technologies came out last week, and, as always, it's worth a look, both because of the general framing it offers about technology trends and because of some specific implications for insurance.

From an insurance standpoint, the two most directly relevant are what TR refers to as "the end of passwords" (yay!) and the growing availability of "synthetic" data to train AI in situations where there isn't enough real data available. But the other eight on the list of 10 are intriguing, too, especially for what they suggest about how we might be able to build on the technologies behind the mRNA vaccines against COVID to make additional, huge advances in healthcare.

The article in TR says, "New forms of authentication will finally let us get rid of [passwords] for good. Instead, we’ll use a link sent via email, a push notification, or a biometric scan.... The process is already underway. Enterprise-oriented companies like Okta and Duo, as well as personal identity providers like Google, offer ways for people to log in to apps and services without having to enter a password. Apple’s facial recognition system has taken biometric login mainstream. Most notably, Microsoft announced in March 2021 that some of its customers could go completely passwordless, and it followed up in September by telling people to delete their passwords altogether."

If you believe the analysis in "A Brief History of a Perfect Future" -- and I do, because I wrote it, along with longtime colleagues Chunka Mui and Tim Andrews -- the email links, push notifications and biometric scans are just the beginning. We'll all be able to increasingly triangulate to verify our identities based on the concept of "something you know, something you are and something you own," and the somethings you are and own will get increasingly numerous and sophisticated -- contact lenses that can identify you to your phone or computer, devices smaller than a grain of rice that you can swallow, even a DNA scan using an app on your phone.

Doing away with passwords will not only save us all time and eliminate the frustration that comes with forgetting and resetting passwords but will vastly improve cyber security. Phishing and other approaches to stealing passwords have provided hackers entree into many organizations, and those risks will diminish for individuals, companies and the insurers that cover them. 

This won't happen overnight -- none of what TR promises will come to fruition this year or even next year -- but the notion of a password-free world is, like most of the promised breakthroughs, close enough to reality that we all ought to be thinking about the implications and perhaps even gaming out the effects.

"Synthetic data" for AI is actually an idea that we've occasionally published on at ITL for a couple of years now -- for instance, "How Synthetic Data Aids in Healthcare" last August, "How to Put a Stop to AI Bias" in February 2021 and "Evolving Trends in a Post-COVID-19 World" in May 2020. (Yes, an article envisioning a post-COVID world almost two years ago was more than a little optimistic.)

Basically, if you're trying to train an AI to spot fraud, for instance, but don't have the massive numbers of actual cases that machine learning requires, you have an AI create lots of "cases" by synthesizing them out of the data you do have. There's an obvious limitation: The synthetic cases are only as good as the information you feed the AI that creates them. If the examples you feed the AI don't include a certain type of fraud, well, then the synthetic data won't, either. But AI developers are still finding synthetic data useful. 

As TR explains the concept of synthetic data: "Training AI requires vast amounts of data. Oftentimes, though, that data is messy or reflects real-world biases, or there are privacy concerns around the information included. Some companies are starting to create and sell synthetic data to avoid these problems. It’s not perfect, but it could be a better way to train AI."

Some of the breakthroughs that TR predicts could have significant implications for COVID, for future pandemics and for other diseases. For instance, TR says the massive investment in genomic sequencing that undergirded the mRNA vaccines against COVID is allowing for much better tracking of the virus and its variants.

The work has even produced "a pill for COVID." TR says, "Given to people within a few days of infection, an antiviral from Pfizer slashes the chance of hospitalization by 89%. The U.S. government has already placed orders for $10 billion worth of the new drug, called Paxlovid.... Pfizer’s drug could also be a ready defense against the next pandemic."

TR also holds out great hope for a vaccine for malaria, which kills more than 600,000 people a year, most of them younger than five. The GlaxoSmithKline vaccine, approved last October by the World Health Organization, is still in its early days. TR says, "It requires three doses in children between five months and 17 months old, and a fourth dose given 12 to 15 months after that. Given to more than 800,000 children in Kenya, Malawi, and Ghana, the vaccine had an efficacy of about 50% against severe malaria in the first year, and its effectiveness dropped dramatically over time." Still, combined with other measures, such as bed netting treated with insecticides, the vaccine "is expected to reduce malaria deaths by as much 70%, compared with the death rate in children given existing drugs," TR says. That could mean hundreds of thousands of lives saved each year, and second-generation vaccines are already on the way. The vaccine, which is the world's first for a parasitic infection, also holds out hope that others can be beaten back, too. 

Citing potentially even broader implications, TR singled out the work by DeepMind that has allowed AI to predict how proteins will fold themselves, removing the need to use a complicated chemical process that could take a year and cost $120,000 just to determine the shape of a single protein. Knowing the shape, and not just the sequence of acids in the protein, is key to understanding how proteins interact with other and, perhaps, with drugs that might halt or reverse a disease. I was so intrigued when DeepMind made its initial announcement in late 2020 that I wrote about it at the time, and the subsidiary of Alphabet has made remarkable strides since then.

The shape of some 170,000 proteins had been determined chemically over many years when DeepMind made its initial announcement. TR now says, "DeepMind has... set up a public database that it’s filling with protein structures as AlphaFold2 predicts them. It currently has around 800,000 entries, and DeepMind says it will add more than 100 million—nearly every protein known to science—in the next year."

Finally, TR holds out some hope on climate change. It describes promising developments in grid-scale batteries -- the sort that will be needed to ensure smooth provision of electricity as renewables are increasingly integrated into our electricity supply. TR also describes the opening of a plant in Iceland that is the largest to date that removes carbon dioxide from the air. Again, this is just baby steps. The facility can capture 4,000 metric tons a year -- about the output of 900 cars -- while the world produces some 51 billion metric tons. And the cost per ton removed is $600 to $800, while it needs to be $100 a ton or even lower to be broadly practical. But bigger plants are on the way, and, importantly, some companies are willing to pay today's high costs as they strive to cancel out their emissions. Those companies are providing crucial revenue that will help carbon removal efforts scale. TR even touts a major improvement in the magnets that are needed to contain the super-hot plasma required for nuclear fusion, which has long been the Holy Grail because it would provide us the energy of the sun without the radioactive waste that comes from nuclear fission.

Having written a great deal about climate in "Perfect Future," too, I think these technologies will kick in further down the road -- especially in the case of fusion -- than the others, so I won't go into them at length here. But I encourage you to read the TR piece. I always find their annual list stretches my thinking and opens up possibilities.

Cheers,

Paul


A Patient-Centered Approach to Claims

Properly applied, AI produces better medical outcomes, gets employees back to work faster, reduces litigation risk and lowers the costs associated with claims.

claims management

As a physician, I can’t help but view our industry through a distinctly patient-centered lens. Our very reason for existing is to help injured employees get well, ideally to get them back to their pre-injury status in days or weeks. When that’s not achievable, we aim to help each worker get the best possible medical outcome given their unique circumstances.

A strong technology foundation can help deliver that kind of patient-centered experience. At first glance, that may sound contradictory. After all, early efforts to automate human-centered processes in other industries often backfired, creating the impression that efficiency often comes at the cost of poor customer service. In today’s world, though, that doesn’t need to be the case. With the right technology, we can deliver much better outcomes than would otherwise be possible.

As time marches on, we’ve learned what works and what does not. Technology improves. We can apply it in new ways. We can work smarter instead of harder. In the context of claims management, we can empower our people to spot potential concerns in a worker’s case, identify the best providers for specific injuries and ultimately deliver better outcomes for injured workers.

Patient-Centered Thinking

When it comes to workplace injuries, the human element remains absolutely critical. A single incident can profoundly affect a person’s life as well as the lives of their loved ones. It can have a lasting impact ranging from chronic pain to disability, depression and even addiction.

By facilitating better medical outcomes, we can get injured employees back to work faster. We can steer clear of the pernicious traps that can lead a patient into a downward spiral, both medically and psychologically. Better, faster medical outcomes are a win-win for injured workers, for their employers and for insurers and policyholders.

We already know about many of the key factors that influence positive outcomes. When a medical professional is involved early in the process, for example, an employee is more likely to recover quickly. But what about some of the more nuanced factors? What are the ingredients for an optimal patient experience?

See also: How to Use AI in Claims Management

Working Smarter

To answer that question, we need to bring greater intelligence to the claims management process. We need to inform and empower the professionals who guide each claim toward a successful conclusion. Today’s technology can help us achieve that. Artificial intelligence (AI) and machine learning give us an edge that we’ve never had before. They help us understand what works and what doesn’t. They help us zero in on the things that matter most by constantly monitoring claims activity and generating customizable alerts for claims managers.

In fact, AI technology isn’t replacing the human element at all. On the contrary, this technology is making it possible to enhance patient care and improve medical outcomes. It’s helping claims professionals to be far more effective.

At Employers, for example, we’re using AI claims management technology from CLARA Analytics to identify the healthcare providers most likely to produce positive outcomes for specific types of patients and injuries. This goes well beyond a “gut feel” assessment; it gives us intensively data-driven recommendations to help identify the best possible provider for each claimant.

The results? When providers are ranked along a five-point scale and matched with specific patients and injuries, the top tier of providers helps workers get back on the job faster, with average medical payments of just over $1,100. Workers treated by providers in the bottom tier average medical costs of over $7,000 per incident. In cases involving indemnity for lost wages, data shows an average of fewer than 30 days of missed work for cases treated by top-tier providers. Injured workers treated by low-performing providers, in contrast, averaged over 570 days of missed work.

AI helps claims managers to be more effective, as well. Consider an example in which a physician’s notes highlight a specific medical complication that could lead to the patient’s prolonged absence from work. For a claims manager tasked with poring through mountains of medical records, injury reports and other documentation, that kind of detail can sometimes slip through the cracks. AI can spot meaningful information virtually the moment it becomes available, then bring it to the attention of an experienced claims manager.

Patient-Centered Care at Scale

This is good news for everyone involved. The even better news is that this works well at scale. AI helps us improve outcomes for injured workers, including those whose cases aren’t managed proactively by their employer. My organization frequently works with very small businesses that generally don’t have the resources to support comprehensive risk management programs. AI enables us to provide a level of high-touch care that employees at these companies would not otherwise receive.

If you ask the average person on the street about the societal impact of AI, you’re likely to hear concerns about the dehumanizing effects of technology and the replacement of workers by intelligent machines. The reality is far different. Properly applied, AI produces better medical outcomes, gets employees back to work faster, reduces litigation risk and lowers the costs associated with claims.

As a physician, that’s something I can feel good about.

As first published in WorkCompWire.


Dwight Robertson

Profile picture for user DwightRobertson

Dwight Robertson

Dwight L. Robertson, M.D., is vice president, managed care and national medical director at EMPLOYERS, America’s small business insurance specialist®. Dr. Robertson has over 30 years of experience in various leadership roles, including chief medical officer and top managed care positions at Travelers, AIG, Coventry, Zenith National Insurance and MSC Group, Inc. Dr. Robertson holds an M.D. from the Duke University School of Medicine as well as an M.A. in public policy from Duke University.

Lemonade: No Sign of Disruption Yet

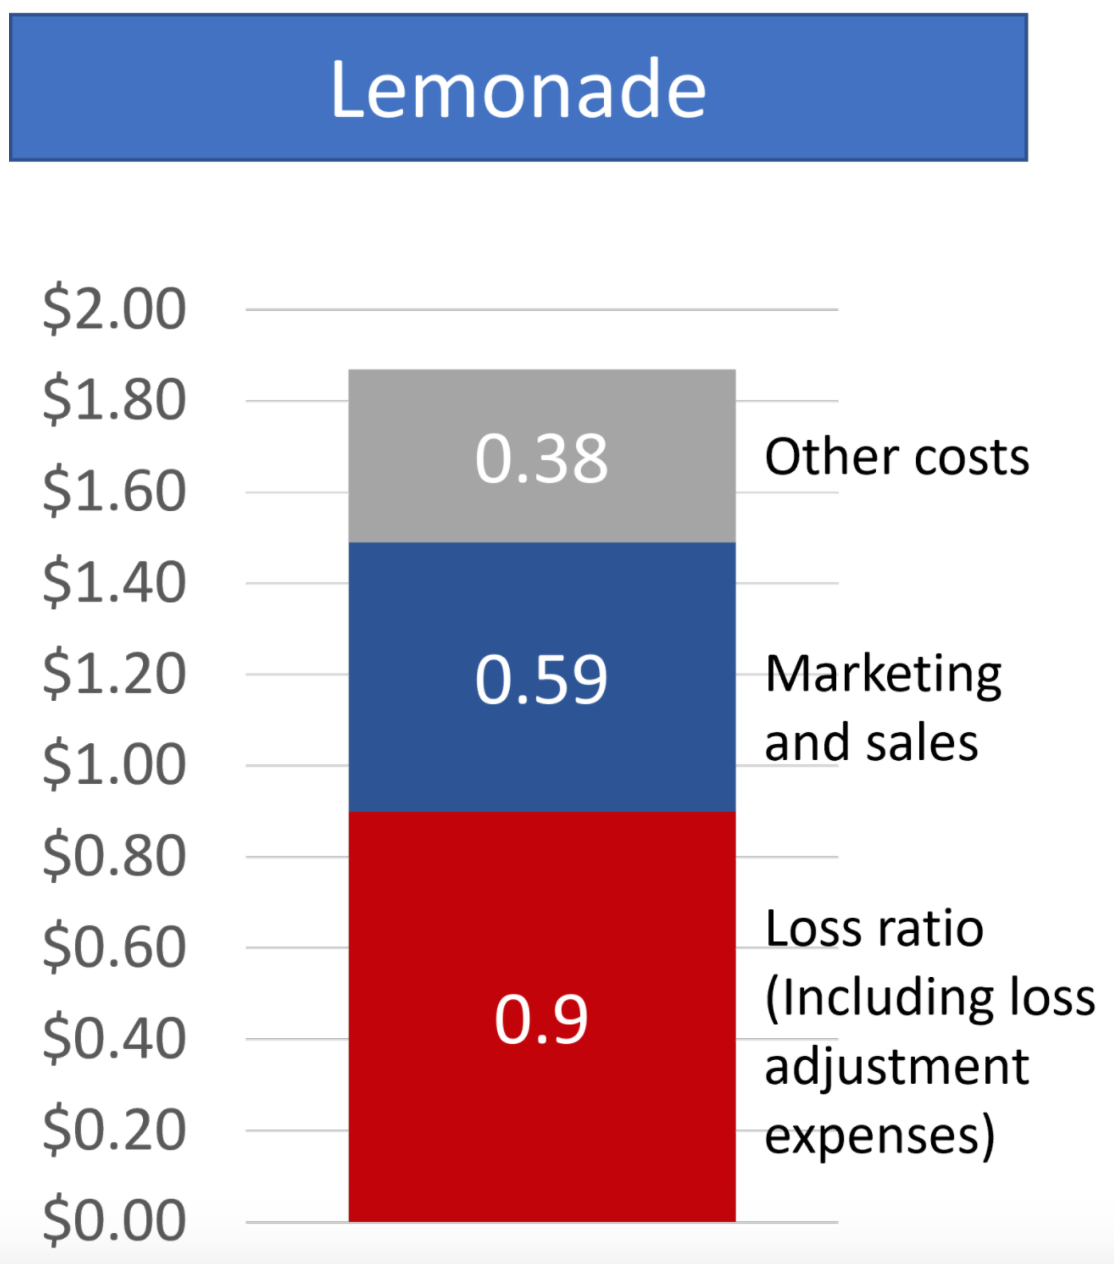
For each dollar of premium, claims cost Lemonade 90 cents, marketing cost it 60 cents and other costs added 40 cents. Feel a little betrayed?

tech

Insurtech has come of age. Just last week, we saw:

I love numbers, and I've crunched insurtech financial numbers for the past few years, so let's have a look.

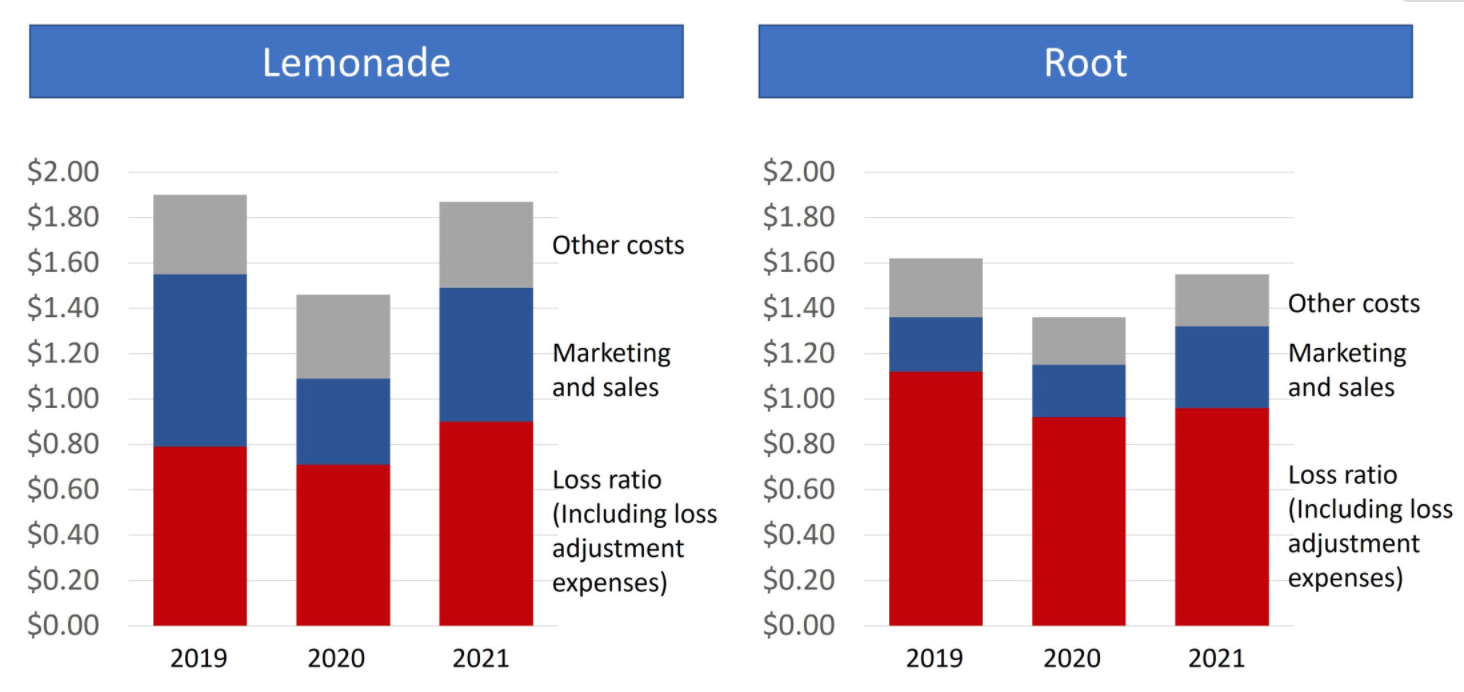
Lemonade has written almost $370 million in premiums (showing 42% growth from 2020), and Root has written more than $740 million in premiums (showing 20% growth from 2020). However, both these full-stack insurtech players have run an insurance business with a combined ratio (gross of reinsurance) above a 150% combined ratio in 2021. This means that, for each dollar of premium paid by the client, the companies' risk transfer approaches a cost of more than $1.50.

Almost the same has happened over the past three years.

chart

How it started

We all remember how Lemonade has fascinated insurance professionals:

lemonae

Lemonade CEO interview in 2017:

"Insiders agree: 'At least 40% of what insurance carriers receive in premiums is paid out in claims. So if Lemonade is 80% cheaper it must lose money on every policy.’ That is not true. Renters insurance covers personal property, not real estate. The expected loss is therefore significantly lower and so should the corresponding premium be. Unfortunately, the enormous overheads incumbents have, make low-premium products impossible. Their minimum premium reflects their high costs rather than your low claims.”

"We apply behavioral economics to neutralize the adversarial relationship, the conflict of interest, between customers and their insurance provider. We take 20%, and the rest (80%) goes to paying claims, and this includes our reinsurance. If less than the 80% is used to pay out claims, for instance 75%, the 5% unclaimed money is donated to charities chosen by customers. The maximum amount that can be given back is 40%. Lemonade gains nothing by refusing a claim. This way, we are reinventing insurance from a necessary evil to a social good."

See also: 10 Insurtech Trends at the Crossroads

Moreover, on their blog:

"That changes everything. Insurers typically make money by investing premiums ('float') or by paying out less in claims and expenses than they took in premiums ('underwriting profit'). Lemonade relies on neither. We collect premiums monthly, so the money earns interest in your bank account, not ours, and we return unclaimed money at year’s end in Lemonade’s Giveback.

"Knowing you’re not in conflict with your insurer, and that you embellish claims at the expense of a cause you believe in, may change your behavior, too, setting off a virtuous cycle. Ultimately, we’re after a new Nash equilibrium, one where aligned interests breed trust, resulting in a product that is inexpensive, hassle-free and lovable."

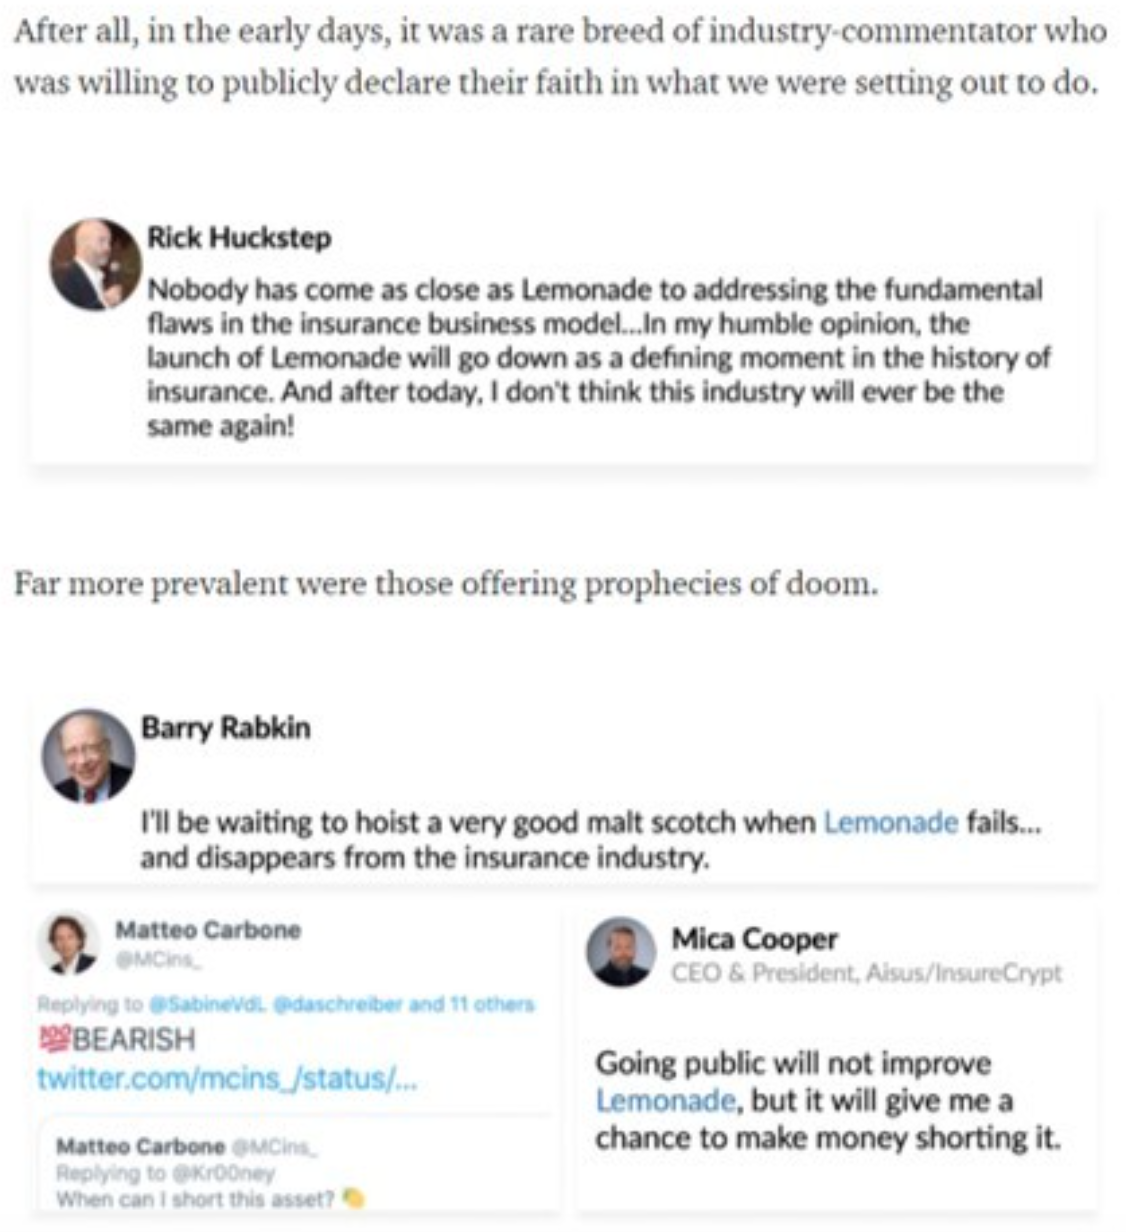
Over these years, I've been pretty skeptical about this storytelling:

text

And I have challenged the sustainability of their financials a few times.

text

They didn't like my analysis so much.

How it's going

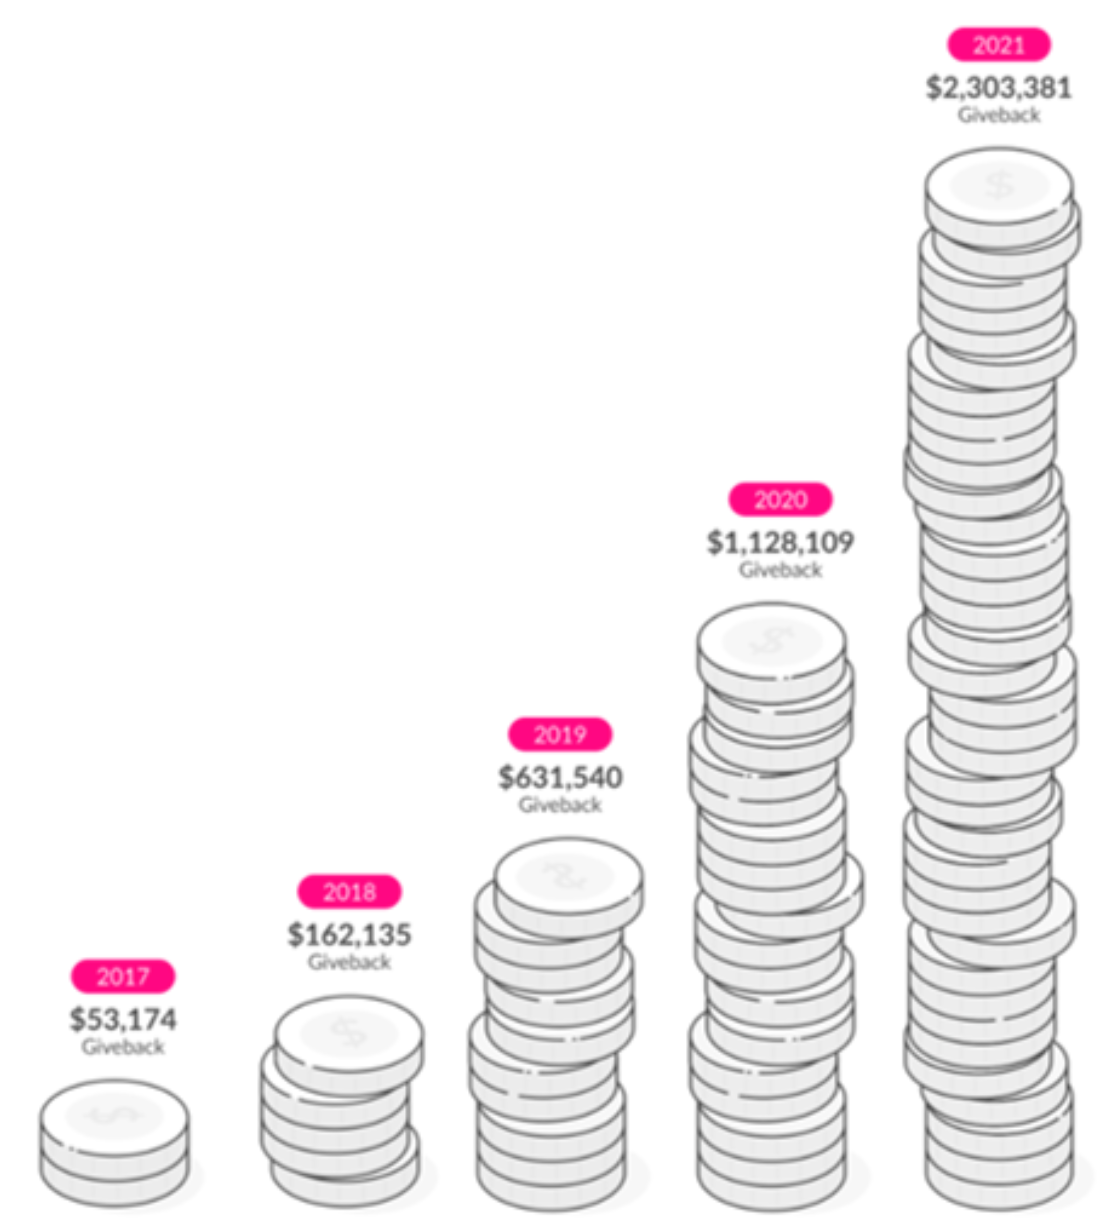
Let's start with the giveback:

chart

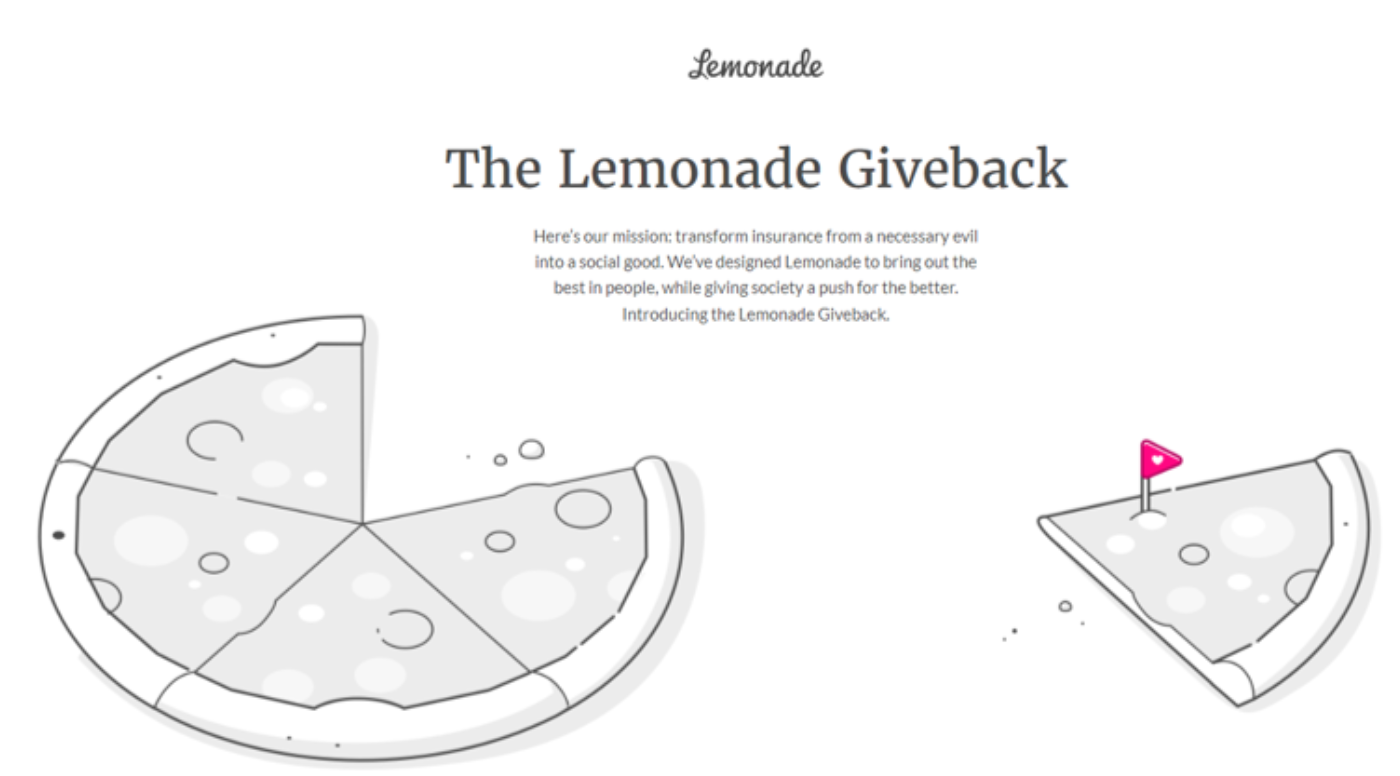
A giveback of $2.3 million accounts for one cent on each dollar of written premium. Pretty different from the expectation given by the iconic pizza slice that characterized their storytelling back in the days.

See also: Game-Changing Trends in 2022 for the Future of Insurance

Let's look at the financials. For each dollar of premium, claims cost 90 cents, including the loss-adjustment expenses. (It seems that old claims have been under-reserved; we could discover in 12 months that even the current year reserves are not adequate). To acquire this (underpriced?) business, Lemonade invested almost 60 cents in marketing for each dollar of premium. All other costs add almost 40 cents.

chart

It doesn't seem that behavioral economics, charity and storytelling have made any dent in the insured risks.

So, all the insurance professionals who fell in love with their disruptive storytelling over the past six years should feel a little betrayed. I see a fantastic team driving a superb marketing machine with a cool front-end... but no sign of disruption yet.

To subscribe to Matteo's LinkedIn newsletter, click here. 

Six Things: February 22nd, 2022

Smart Homes are Finally Getting Smarter. Plus, the power of low-code platforms; a new paradigm for sourcing capacity; and more.

six things header


Smart Homes Are Finally Getting Smarter

Paul Carroll, Editor-in-Chief of ITL

Despite all the hype for smart homes, I've remained a skeptic for the 30 years or so since I first heard about the concept, partly because there wasn't a standard way for all the disparate devices to talk to each other. There wasn't a sort of operating system for the house, and a bunch of one-off devices weren't going to provide enough benefit. 

Well, three of the biggest guns in the tech world -- Apple, Google and Amazon -- just announced a new standard for communication that will be available later this year. The standard, called Matter, will let just about all new smart home devices, and even many old ones, talk to each other. 

Progress will still take time, and I remain to be convinced that many of the long-touted "benefits" of the smart home -- an internet-connected toaster or the ability to turn lights on and off remotely, for instance -- actually offer anything of value, but at least there will finally be a communication platform that will let companies, including insurers, tie all the benefits together and look for synergies.

continue reading >

New Research

Don't miss this new report from Capgemini and Majesco as they leverage insight from recent executive roundtables to dive into the recent workforce changes and its impact on the employee and employer relationship.

Download Report


SIX THINGS


The Power of Low-Code Platforms
by Vinayak Joglekar

Customers now expect exceptional service from all businesses, and low-code platforms hold great promise for businesses’ internal and external users alike.

Read More

A New Paradigm for Sourcing Capacity
by Dogan Kaleli

Capacity-seekers and capacity-providers are starting to recognize the benefits of an organized digital marketplace with an efficient electronic infrastructure.

Read More

Reconfiguring Your Approach to Underwriting

Sponsored by Intellect SEEC

 Explore how companies can lay the groundwork for modernization and innovation by reconfiguring their approach to core systems.

Read More


Predictive Modeling’s New Mantra
by David Zhu

With the power of predictive modeling and its resulting efficiencies, life insurers can simplify underwriting, reducing both time and complexity.

Read More

Getting WC and Long-Term Disability to Mesh
by Heather Garbers

Employers need to build a better bridge between workers' comp and LTD to better manage the common ground between them – the employee’s health.

Read More

Data Modernization Isn't One-Size-Fits-All
by Vaibhav Uttekar

Large and small carriers, in most cases, have inherently different business processes, capabilities and priorities due to their variance in size.

Read More

A Better Approach to Extended Warranties
by Brad Hawkins

Field service management software can digitize steps of the warranty workflow to improve customer satisfaction and provide quality and convenience.

Read More

InsurTech Ohio Spotlight with Ron Rock

Sponsored by JobsOhio 

Ron Rock discusses how the insurance industry is rapidly evolving, and the importance of recruiting and retaining top software and programming talent. 

Read Now


MORE FROM ITL


February Focus: Blockchain

Sponsored by Gigaforce

While blockchain has been an intriguing topic for some time now, interest has skyrocketed in recent months. 

Facebook said late last year that it believes so much in the "metaverse" that it was changing its name to Meta. Microsoft followed quickly with its own vision of how technology could enable a whole new sort of world, where our selves are disembodied and our interactions occur via virtual reality. Venture capital firms such as Andreessen Horowitz are all over the investment opportunities in the metaverse, sometimes referred to as Web 3.0. And pundits are making bold proclamations about how life as we know it is about to change forever. 

Read More

A SMART PATH TO OPTIMIZING IT COSTS

Sponsored by Rimini Street

In this webinar, ITL Editor-in-Chief Paul Carroll sits down with Jim Duggan, vice president, client engagement, global service delivery, at Rimini Street, and Anne Plese, Rimini Street's senior director of product marketing. They discuss how insurers can optimize their data centers and generate savings that can help fund innovation initiatives. 

Read Now


Partner with ITL to create expert thought leadership content.

Custom Content
Promoted Content
Display Advertising
Custom Webinars
Monthly Topic Sponsorships
ITL Partner Packages and more


Learn more and get the 2022 Media Kit


Insurance Thought Leadership

Profile picture for user Insurance Thought Leadership

Insurance Thought Leadership

Insurance Thought Leadership (ITL) delivers engaging, informative articles from our global network of thought leaders and decision makers. Their insights are transforming the insurance and risk management marketplace through knowledge sharing, big ideas on a wide variety of topics, and lessons learned through real-life applications of innovative technology.

We also connect our network of authors and readers in ways that help them uncover opportunities and that lead to innovation and strategic advantage.

Mixed Signals on the Industry’s Prospects

So, even if interest-rate pressures diminish, insurers may feel the need to keep pulling every possible lever to become more efficient, including with agents and brokers. 

a graphic representing home, life, auto and umbrella insurance

Although I haven’t seen much written yet on what rising interest rates will do to the insurance industry, the trend has to be a positive – even as other signals stay negative. 

Insurers have for some years now fretted about what low interest rates are doing to the returns on their massive investment portfolios. So, it has to be a welcome prospect that the Fed will raise interest rates multiple times this year – Morgan Stanley recently predicted six increases, each of 25 basis points, or hundredths of a percentage point.  

The lack of return on the investment portfolios has forced insurers to press harder elsewhere. The area that I hear most cited is underwriting, where firms are imposing discipline to make sure they return a profit as long as they can’t count on investment returns to cover any failings. But insurers have felt pressure to create efficiencies across the board, including in the distribution channel. So, any easing of pressure because of a rise in interest rates should tend to alleviate some of the more drastic actions insurers might be contemplating.  

Likely good news for agents and brokers! 

At the same time, McKinsey is making ominous noises about how the industry is faring. As summarized in Reinsurance News a recent report from the management consulting firm said that insurance industry profits are “practically at a standstill.”  

The report said that premium growth slowed from more than 4% in 2020 to just 1.2% last year and that earnings dropped 15%. More ominously, McKinsey concludes that half of insurers around the world aren’t earning their cost of capital.  

So, even if interest-rate pressures diminish, insurers may feel the need to keep pulling every possible lever to become more efficient, including with agents and brokers. 

Of course, we’re all still wrestling with the pandemic, and we all may have even bigger worries soon enough, given the Russian decision to invade Ukraine. Here’s hoping the pandemic and geopolitics settle down enough that we can actually focus on limited issues like interest rates and premium growth, rather than having to figure out existential ones.  


Paul Carroll

Profile picture for user PaulCarroll

Paul Carroll

Paul Carroll is the editor-in-chief of Insurance Thought Leadership.

He is also co-author of A Brief History of a Perfect Future: Inventing the Future We Can Proudly Leave Our Kids by 2050 and Billion Dollar Lessons: What You Can Learn From the Most Inexcusable Business Failures of the Last 25 Years and the author of a best-seller on IBM, published in 1993.

Carroll spent 17 years at the Wall Street Journal as an editor and reporter; he was nominated twice for the Pulitzer Prize. He later was a finalist for a National Magazine Award.

Getting to the Next Level in IT Systems

Even if legacy systems are occasionally updated, a completely new way of looking at the system as a whole is needed. This is where DevSecOps comes in.

office workers

Many legacy insurance companies established their internal technological infrastructure a long time ago, and, even if these systems are occasionally updated, a completely new way of looking at the system as a whole is needed. This is where DevSecOps comes in.

DevSecOps is the next iteration of DevOps, the combination of software development and IT operations. The "Sec" in the new iteration is for "security," whose concerns are incorporated throughout the development pipeline to optimize internal processes and create high-quality, secure releases. Insurance companies handle large amounts of sensitive information. Properly securing this data is paramount to protecting clients as well as remaining in compliance with data security regulations.

But how does a DevSecOps pipeline directly address the unique concerns of the insurance industry?

Let’s look into these three ways DevSecOps helps propel insurance companies forward:

1. Streamline Processes

Many things need to happen to bring an update or application from planning through deployment. The initial spark of a new development project is likely something as simple as noticing a hole in the industry—a need that is going unfulfilled.

DevSecOps provides a framework by which your team can quickly and securely move an idea through production while ensuring all of your bases remain covered.

Redundant tasks, errors found late in the pipeline and repetitive manual tasks are a drain on productivity, so automated tools are a huge part of an optimized DevSecOps pipeline. Various tools address different parts of the pipeline but work together to reduce errors and speed a project toward deployment without sacrificing quality.

The customers’ expectations are constantly evolving. Frequent and reliable development releases are the only way to provide these capabilities to customers. Insurance companies that can be trusted to offer continued access to these services will be seen as market leaders.

Automation, team collaboration and other DevSecOps practices are widely recognized for their ability to optimize the Salesforce development release process.

See also: Key Considerations for Managing Innovation

2. Enhance Code Quality

DevSecOps includes multiple quality checkpoints with the goal of ensuring proper code structures, reducing errors and improving the experience for your end user.

Insurance companies simply can’t allow improper functionality to enter their system and potentially affect data pools. 

Data and metadata influence our working environments in many ways—including defining how certain fields relate to each other. For instance, filling in a customer’s name in one field might bring up their address in another field. A failure to properly link these two fields can create large problems.

Tools like static code analysis and CI/CD enable team members to produce the highest-quality code without sacrificing large amounts of time to manually verify coding structures.

Data sets in the insurance industry can be huge. A data governance plan will involve the efforts of various sections of a company. 

DevSecOps processes incorporate the efforts of various teams to arrange essential data into workable sets. The data can then be incorporated into processes and future developments to provide various benefits:

  • Reduce errors
  • Improve planning for future updates
  • Provide useful analytics
  • Assist successful deployments
  • Deliver actionable feedback

3. Remain Secure and Compliant

Cyberattacks are becoming increasingly prevalent. In fact, businesses suffered 50% more cyberattack attempts per week in 2021. These attacks can be disastrous for any company. Insurance companies, however, run the risk of exposing all of their customers’ sensitive information on top of the massive costs associated with experiencing a data loss.

The threats against a company’s systems are constantly changing. Our responses to these threats need to be continually evolving, as well. 

See also: Don't Just Indulge in “Innovation Theater”

A streamlined DevSecOps pipeline enables insurance companies to quickly release patches, updates or other security applications to stay on top of emerging vulnerabilities. Secure releases with reliable coding structures are an essential aspect.

Protecting this sensitive information is incredibly important. This is why data security regulations exist. Companies that operate with sensitive information—such as the insurance industry—are required to take adequate measures to protect it.

Documentation of data access, records kept and any breaches to your Salesforce system can be implemented through proper DevSecOps processes.

Handling and storing system files, metadata and customer personal identifiable information (PII) is essential to remaining compliant. DevSecOps strategies imbue every step with an eye toward proper handling of this information.


Tim Van Ash

Profile picture for user TimVanAsh

Tim Van Ash

Tim Van Ash leads the product and engineering organization at AutoRABIT, the leader in CI/CD and data protection for the salesforce.com ecosystem. Van Ash has spent 25-plus years leading product teams, engineering, strategy, marketing, presales and consulting.